We took 3,096 recordings of New Zealand birds from Xeno-Canto and studied the voices of three species, each with its own scheme from the literature: tūī syllables (Hill & Ji 2014), korimako (bellbird) syllables (Webb 2021) and kākā calls. Where an automated label did not survive checking, it is not shown.
Bioacoustic replication · after Hill & Ji (2014) · 177 species · 3,096 recordings
Source: Xeno-Canto API v3 · Analysis in Python (librosa, scikit-learn) · Full pipeline on GitHub
Compiled by Matilde & NimbleCo AI · June 2026
3,156
Recordings (XC + Koe)
177
Species
326
Songs detected
47
Calls detected
Scope
This is an extended replication of Hill & Ji (2014) using crowd-sourced field recordings. We analysed all 232 tūī A-quality songs, 94 korimako, and 47 kākā recordings, with geographic variation across 10 regions. Discrepancies with Hill's manual classification are discussed. Every claim we corrected or withdrew along the way is logged under Process.
Each species sings its own language. This analysis uses species-specific classification schemes drawn from the published literature —
tūī syllables follow Hill & Ji (2014), korimako syllables follow Webb et al. (2021) and Roper et al. (2018), and kākā calls
are mapped without call-type labels, because our automated labels failed validation. Categories are never shared across species.
Why separate species? Tūī and korimako are both oscine passerines (songbirds) that produce complex learned songs —
but their vocal repertoires are categorised differently in the literature. Tūī research uses 6 syllable categories based on
spectral features. Korimako researchers found that syllable types (not song types) are the functional units of vocal culture,
because korimako flexibly recombine syllables. Kākā are parrots, not songbirds — they produce calls, not songs, and the term
"syllable" is inappropriate for their vocalisations.
Species-Specific Results
Tūī — 6 Syllable Categories
RMNR dominates at 64.7% — rapid multiple note repetition is the most common syllable type.
Trill accounts for 17.5%, harmonic 13.8%, high-frequency 3.3%, and low-frequency just 0.6%.
No harsh syllables were detected, which may reflect recorder bias (harsh syllables are quiet and close-range).
232 recordings · 36,268 syllables · Hill & Ji (2014)
Korimako — 7 Syllable Families
Stutter syllables dominate, at 56.1%. Click follows at 24.1%, then trill 12.6%, complex 3.8%, warble 3.3% and pipe 0.1%.
The 15ms syllable boundary (Roper 2018) captures finer segmentation than the 20ms tūī threshold.
These are rule-based figures from Xeno-Canto; the larger Koe corpus analysis is under Vocalisations.
94 recordings · 13,086 syllables · Webb et al. (2021)
Kākā — Unsupervised Call Space
No call-type labels. Kākā calls are shown as an unsupervised acoustic map:
every call placed by its 52 acoustic features, explorable point by point in the
Vocalisations tab. The rule-based labels we tried (snicker / bark / gurgle) failed
validation and were removed. Labels return when a classifier has been trained against
human-verified examples.
47 Xeno-Canto recordings · 1,790 calls · features per Campbell ARU protocol · +106 staged Macaulay units
Why Species Must Not Be Lumped
Tūī and korimako are both honeyeaters (Meliphagidae) and songbirds, so comparing syllable entropy
between them is defensible — with caveats about different classification granularity. But kākā are
parrots (Psittaciformes) with fundamentally different vocal learning mechanisms, repertoire size (5 call types
vs hundreds of syllable types), and vocal structure. Cross-species comparison between songbirds and parrots
is, as Socrates would say, not carving nature at its joints.
Interactive Tools — Try It Yourself
Beyond the literature-derived categories here, we built two companion tools on the
hand-labelled Koe bellbird data. The PCA clustering tool
plots 818 syllables spike-sorting style across linked principal-component panels — lasso, inspect
spectrograms, play audio, and assign categories. The annotation tool
lets collaborators match candidate syllables to reference templates, with password-based sync so
multiple people can contribute without a GitHub account. This data-driven work seeded the
DTW template-matched categories shown in the Vocalisations tab.
Fourteen native and endemic species with the most Xeno-Canto recordings. Photos from Wikimedia Commons (CC/public domain).
The Pipeline: field recording to individual bird
The korimako results come out of one sequential pipeline. Raw field audio goes in;
named individuals come out. Each stage is validated on held-out birds before the next stage
uses its output. Call-producing species like kākā need a different path (proposed below),
because sequence grammar carries individual identity in songbirds but not in calls.
1 · Field audio48 kHz WAV 2,137 songs 1,065 birds with syllables
2 · SegmentationTweetyNet v2 (CNN) F1 0.902 @ 50 ms 165-song held-out test
Vocal learning — the ability to acquire vocalisations through imitation rather
than instinct — is rare among animals. In the entire animal kingdom, only three groups of birds
(songbirds, parrots, and hummingbirds) share this capacity with humans
(Hyland Bruno et al. 2021).
This convergent evolution makes birdsong one of the most powerful natural models for understanding
how brains learn, produce, and culturally transmit complex vocal behaviour — including human speech
(Aamodt, Farias-Virgens & White 2019).
Detailed vocalisation analysis is how researchers decode this system. By classifying vocal units
and measuring their diversity, sequencing, and geographic variation, we can ask: How complex is a
species' repertoire? Does it vary between populations? What does vocal complexity signal about
ecology and social structure?
Songs vs Calls
The traditional distinction (Catchpole & Slater 2008):
songs are longer, more complex, often learned vocalisations typically associated with
territory defence and mate attraction; calls are shorter, simpler, and often innate — used
for alarm, contact, and flock coordination. In practice the boundary blurs, especially in
Southern Hemisphere species, but the distinction matters for analysis: tūī and korimako produce
songs built from syllables, while kākā produce calls of distinct types.
Song Structure: Syllables, Motifs, and Call Types
Birdsong is hierarchically structured (Berwick et al. 2011).
A syllable is the smallest discrete vocal unit — a continuous sound bounded by silence.
Syllables combine into motifs (repeated stereotyped sequences), and motifs into songs.
Different species organise these units differently: tūī songs contain hundreds of syllable types
in flexible sequences, while korimako researchers found that syllable types (not song types)
are the functional units of vocal culture, because korimako flexibly recombine syllables across songs.
Parrots like kākā don't produce songs at all — they use distinct call types, each serving a
different social function.
Kākā: What are the calls for?
Van Horik, Bell & Burns (2007)
found that each kākā call type serves a distinct social function tied to spatial context:
snicker calls are used during close-range social interactions and copulation;
shraak calls carry over long distances for flock coordination between widely separated birds;
bark calls serve as alarm or alert signals; and gurgle calls are associated
with social bonding. (This is the ethology from the original paper. We do not label calls with these types automatically.) The call repertoire is tuned to communication at different distances —
from intimate contact to forest-wide coordination.
3D Acoustic Manifold — Interactive
Each point is one syllable, embedded in 3D by acoustic similarity (UMAP over the spectral
descriptors from our pipeline). Islands of points are the bird's syllabic textures — an acoustic
signature you can orbit. Click any point to hear that syllable, or play the whole song
through the manifold with highlights synced to the real syllable onsets. The default view is a
korimako song segmented and typed by the pipeline above; tūī examples from the
rule-based pipeline are in the dropdown.
Drag to orbit, scroll to zoom.
Independent open reimplementation of the "Seeing Birdsong" concept (L. Arese), built on our own
descriptor pipeline + UMAP. Embedding trustworthiness 0.90–0.98 across the featured recordings.
Classification follows Hill & Ji (2014) — 6 syllable categories identified from visual spectrographic
inspection of tūī at Tāwharanui Regional Park. Syllable boundaries defined by ≥20ms silence gaps.
44.1 kHz sampling rate, frequency range 500–10,000 Hz.
Syllable Type Distribution
36,268 syllables · 232 recordings · Classifier: Hill & Ji (2014), DOI: 10.63172/301002sqblid
Reading this
RMNR (64.7%) is the dominant category, followed by trill (17.5%) and harmonic (13.8%).
Low-frequency syllables are rare (0.6%), consistent with Hill's finding. These proportions held
when the sample doubled from 116 to 232 recordings. No harsh syllables were detected; these are quiet,
close-range vocalisations that field recorders may not capture.
Category Definitions
Category
Count
%
Definition (Hill & Ji 2014)
RMNR
23,459
64.7%
Rapid multiple note repetition — rapid series of short amplitude pulses
Trill
6,354
17.5%
Rapid frequency modulation — oscillatory f₀ pattern
Harmonic
5,007
13.8%
Integer multiples of fundamental frequency — clear harmonic structure
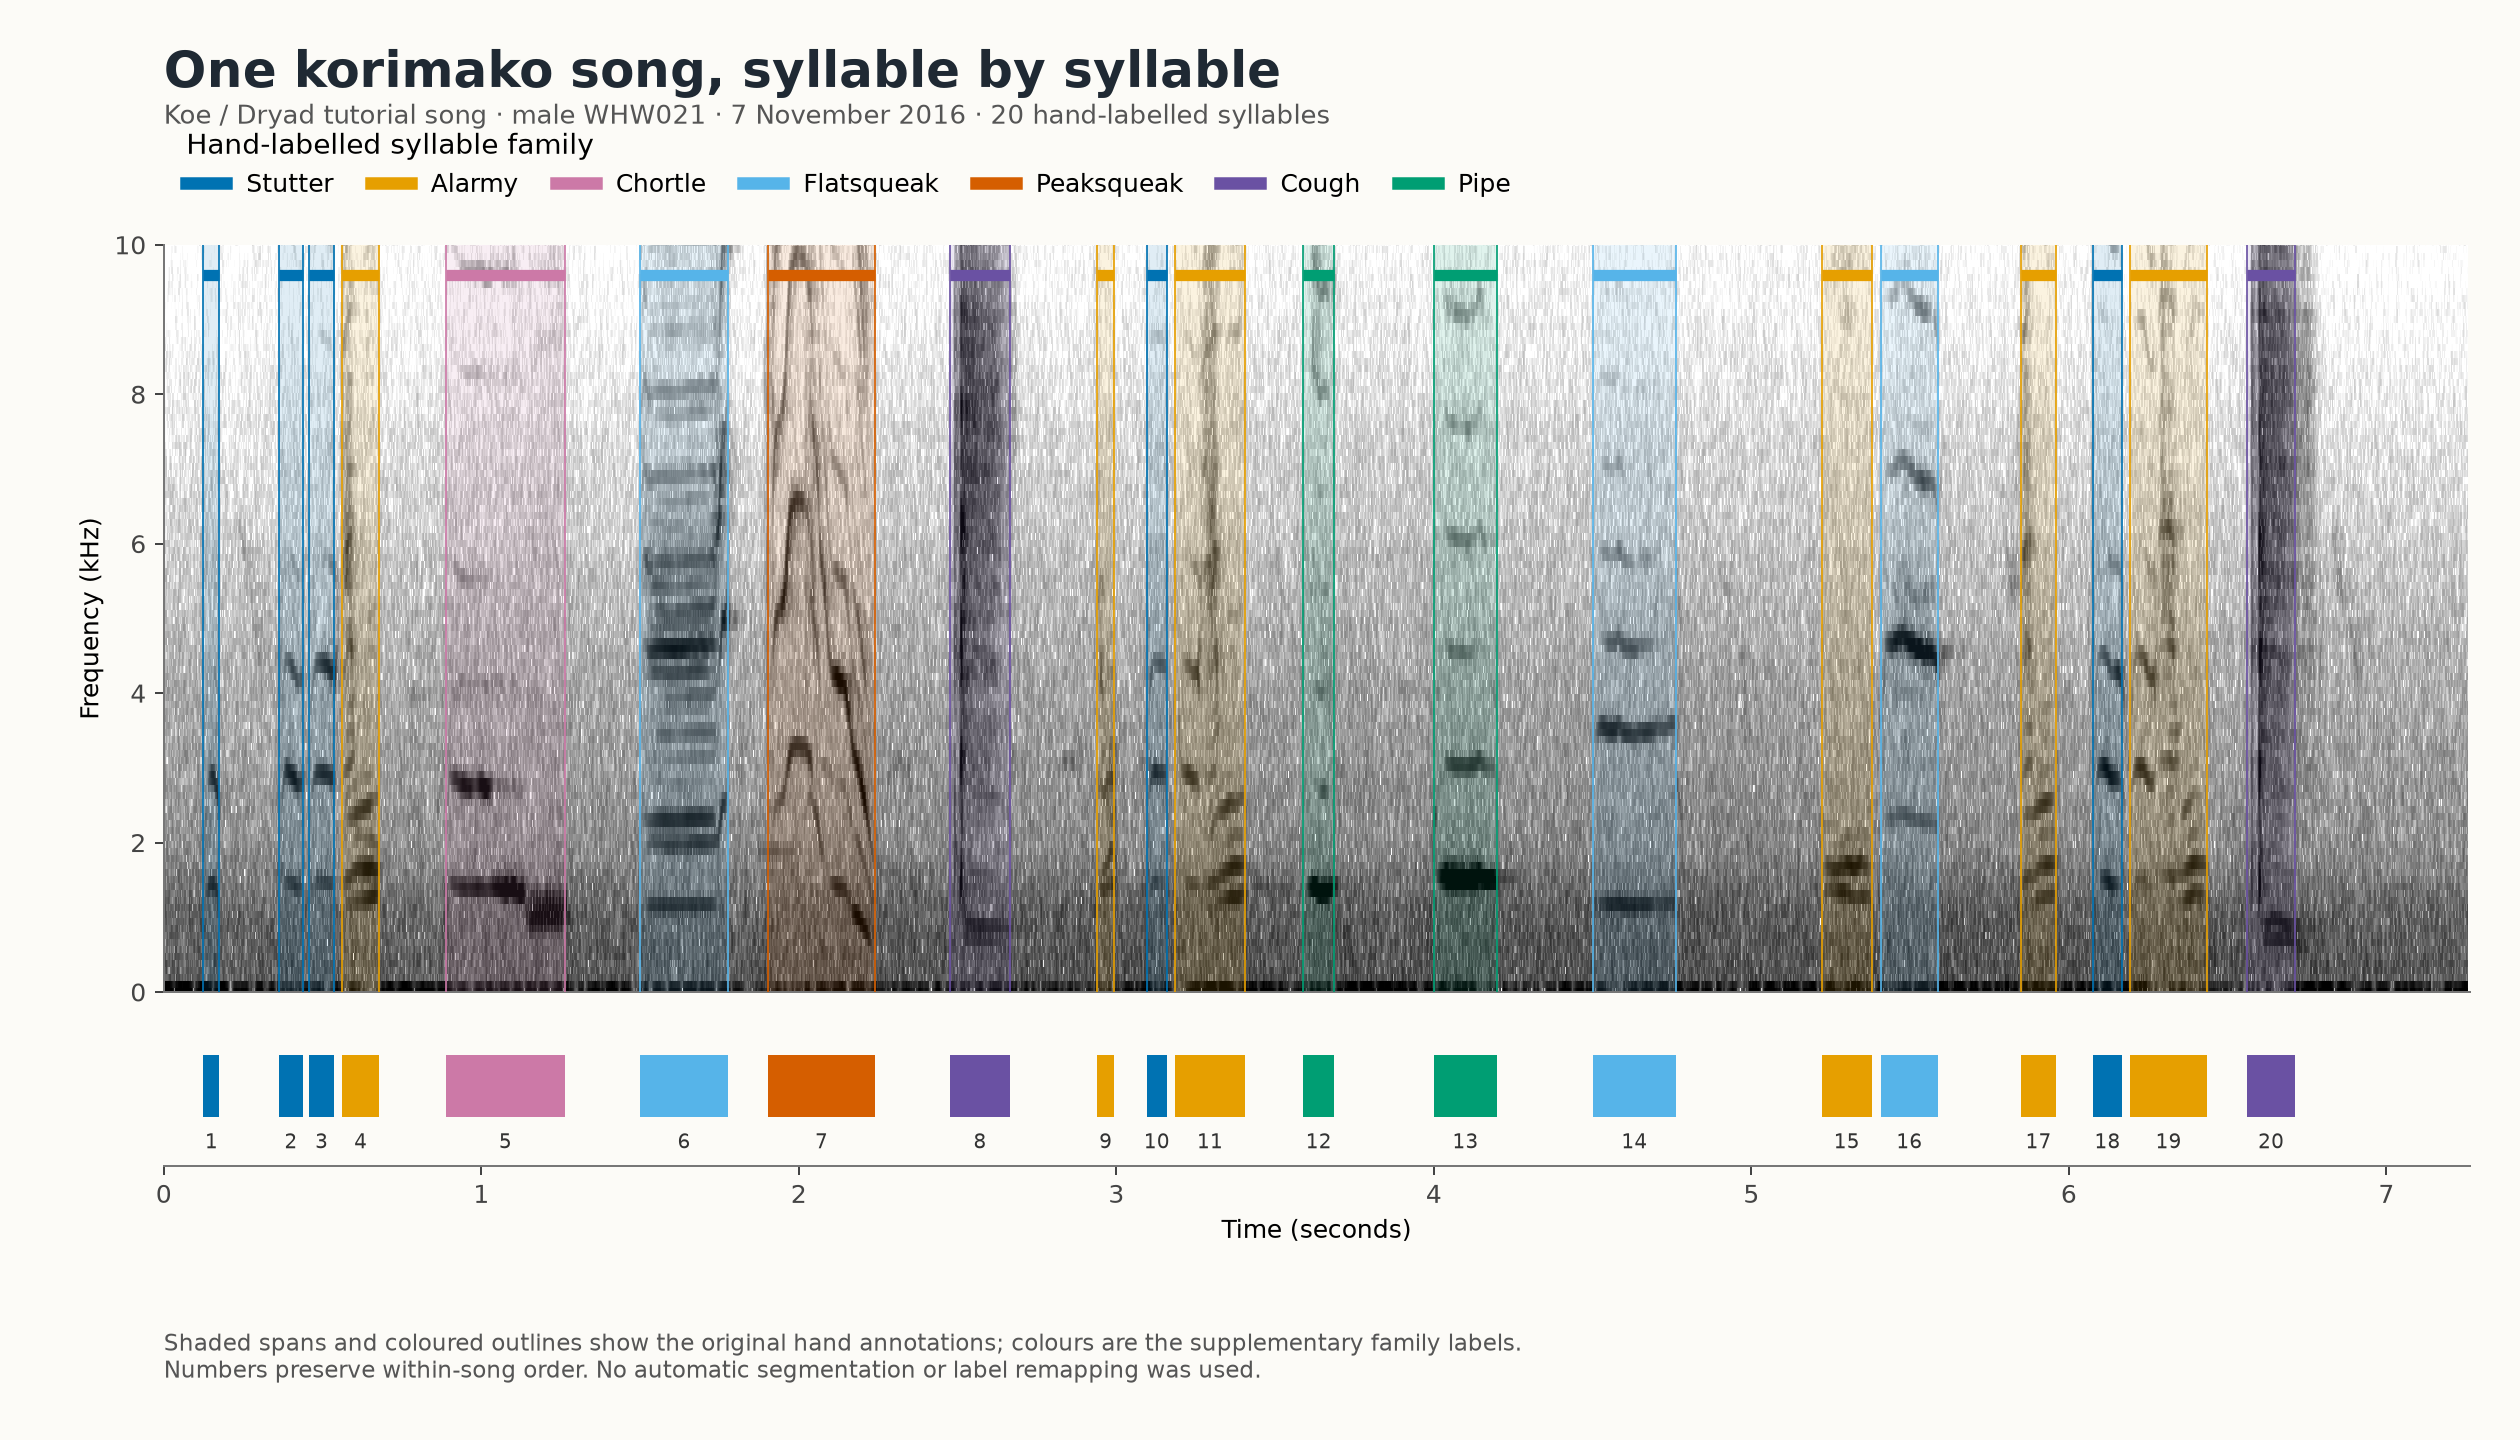
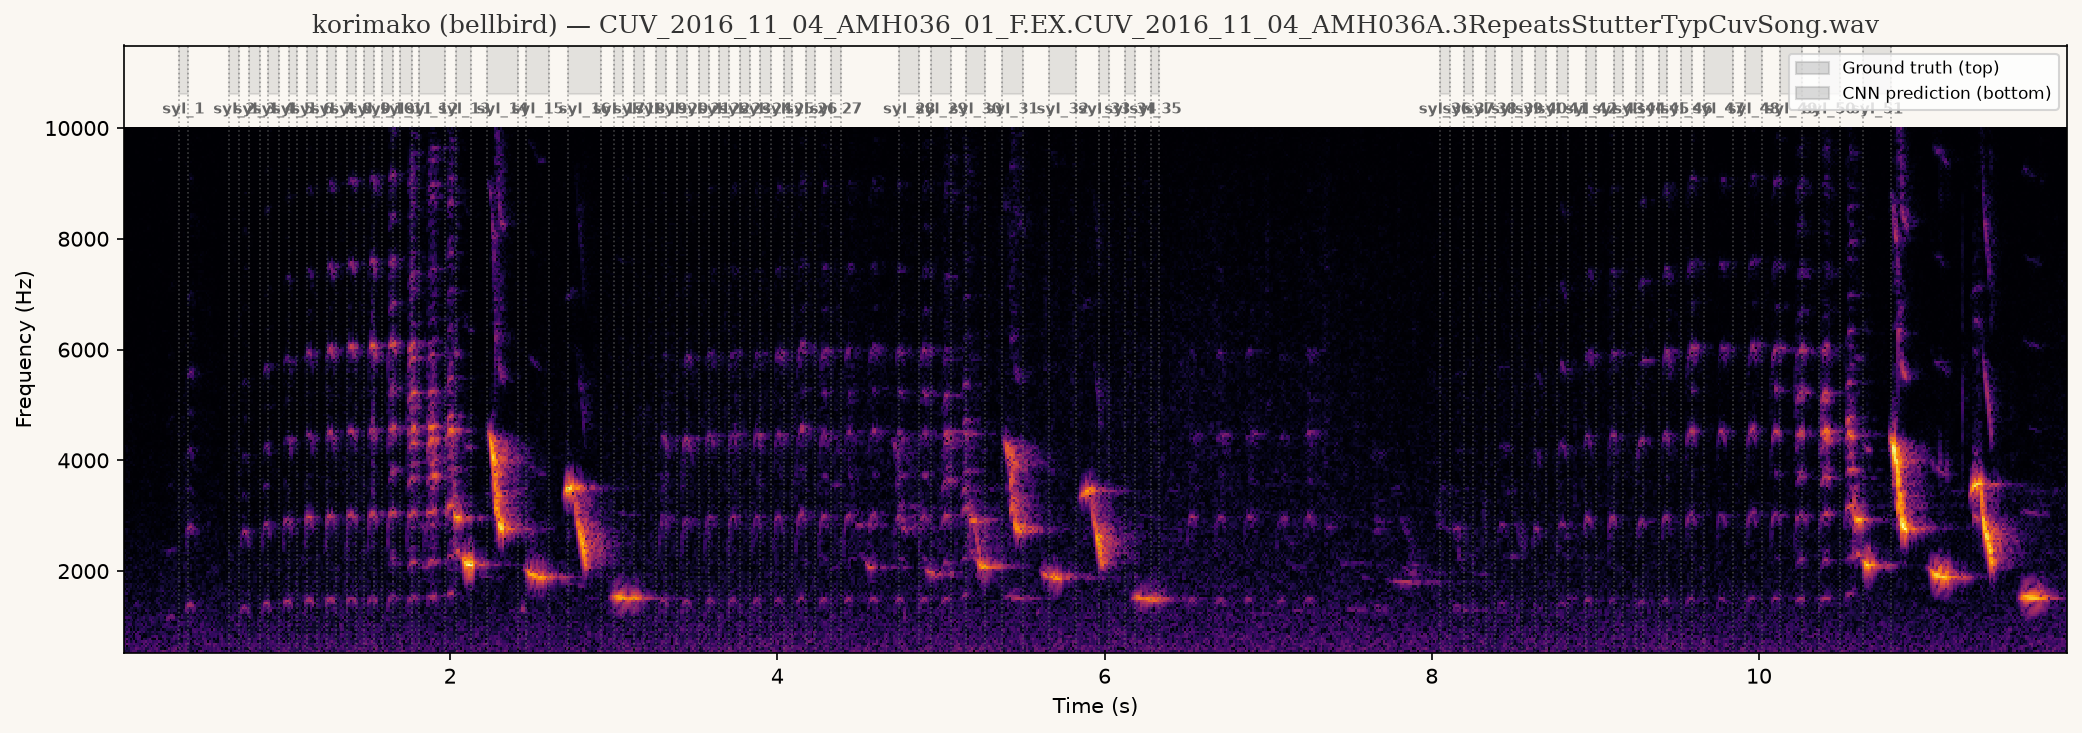
One song, before the model. Twenty hand-labelled syllables from a korimako song by male WHW021 (7 November 2016), from the Koe / Dryad tutorial subset. Colours show the original family labels in Webb et al. (2021), Supplementary Data 3; shading marks the hand-annotated time spans. This is an expository example, not an automatic segmentation or one of the model-extracted results below. Open the image for the full-resolution figure.
Korimako at full scale: 2,136 songs
The figures below use the full Koe corpus:
21,463 model-extracted syllables across 2,136 songs from 1,065 birds (one of the 2,137 songs produced no syllables), segmented by a CNN
(TweetyNet v2, F1 = 0.902 @ 50 ms on a 165-song held-out test, bird-disjoint split) and typed by a
family classifier (0.893 test accuracy on held-out birds). Counts are model-extracted,
not human-labelled. An earlier, smaller hand-labelled analysis is folded away at the bottom of this panel.
Sex from song — does it hold at scale?
Recomputed on the full corpus (454 birds: 234 male, 220 female) using syllable-sequence features
(repertoire composition, family-to-family transition grammar, timing). …
The per-island pattern is consistent with the earlier small-sample run — large well-sampled sites
hold up, small or atypical sites remain hard — so the site-confound story is structural,
not a small-sample artefact.
Repertoire by site — what does each island sing?
Syllable-family composition per site across the full corpus. Computed on model predictions across
1,065 birds (21,463 syllables); the models saw some of these birds in training — the
supplementary tab below repeats every figure on only the 107 test-split birds the models never saw.
(The sex-from-song model above and sex-atypical figure below use a stricter ≥10-syllable-per-bird
subset: 454 birds full-corpus, 37 test-only.)
Sex & repertoire within each site
Korimako are one of the rare songbirds where both sexes sing complex song — and the sexes
share only a fraction of syllable types within a site. Per site: mean repertoire composition for
male vs female birds (full corpus, model predictions).
Non-binary & sex-atypical individuals
Each bird scored P(male) from its syllable repertoire (5-fold cross-validation, so no bird is scored
by a model that saw it). A bird's position on the axis is a stable individual trait. Two groups of
interest: intermediate birds (reliably mid-axis) and sex-atypical birds (song squarely
in the opposite sex's range).
Distribution — where do all birds fall on the P(male) axis?
Stacked histogram of every bird's P(male), split by the bird's hand-labelled sex.
A well-calibrated model piles males at the right and females at the left; the middle band is
where intermediate and atypical birds live.
Distribution — the atypical & intermediate birds specifically
Named examples — intermediate & sex-atypical, well-recorded birds only
Restricted to birds with ≥4 songs, because a bird with 1–2 songs can land anywhere on the
axis by chance. The gold standard is ≥8 songs (the learning-curve threshold for a reliable
per-bird estimate), and the corpus is thin here: most
intermediate/atypical birds have 1–2 songs, so few make the cut. CI = Wilson half-width on
P(male); wide intervals mean trust the position less.
Geographic dialect — repertoire identifies home island
A bird's syllable repertoire identifies which of the six study sites it came from at
… — real dialect structure, though not a substitute for geotags.
Individual ID — which bird is singing?
From a single song, the model names the correct bird … of the time and places
the correct bird in the top five … of the time, across a 77-bird population
(chance = 1.3%). This is closed-set identification — naming a bird from a known population.
Identifiability varies by individual: about a third of birds are reliably nameable, a quarter
effectively never. The learning curve below answers the practical question: how many recordings
per bird does reliable ID need?
Explore: every song as a point, coloured by bird
Each point is one whole song (1,496 songs), positioned by the same features the ID model uses —
repertoire + sequence grammar + timing. Songs by the same bird clump together; that clumping is
how individual identification works. The 20 best-recorded birds are coloured; the rest are grey.
Drag to rotate.
colour by:click a point to play its song
loading…
Unsupervised syllable call-space — no labels, no rules
Every syllable embedded by its 52 acoustic features alone — no family labels, no classifier, no
rules involved in forming the clusters. Colour it by the unsupervised clusters, then toggle
to family (stage-4 classifier labels, Webb taxonomy) and see how much of the human taxonomy
the unsupervised structure recovers on its own — or colour by bird / site / sex to check the clusters
don't just track who or where. Includes the 241 human-verified syllables (Raven-style manual
annotation) and 6,114 archive-staged syllables (94 Xeno-Canto + 9 Macaulay Library
recordings, segmented by the same Koe-validated segmenter and projected in; hollow dots,
with outside-envelope units ringed in red — the channel/quality flag). Click any Koe dot
to play the syllable in song context; archive dots link to their source recordings.
hover a dot · click to play
3,241 Koe (of 19,815; human-verified always shown) + 6,114 archive-staged (94 XC + 9 Macaulay, TN v2-segmented) · UMAP (n=30, min_dist=0.3) on standardised 52-dim features · clusters: HDBSCAN on t-SNE(3d), ms=25/mcs=50 · archive points: hollow, outside-envelope dashed-red
Validation & confound battery (click to expand)
Does the unsupervised structure match the labels? Cluster–family agreement
(ARI, known-family syllables only): 0.222. On the 241 human-verified syllables the
correspondence is much sharper — e.g. Cough 24/24 into one cluster, Chortle 24/24, Peaksqueak
19/19, Stutter 74/79 — while the corpus-wide number is diluted by classifier noise and by
families that genuinely grade into each other.
Confound battery (every grouping tested identically): cluster vs individual
0.014, vs site 0.040, vs sex 0.010. The clusters do not track who
sang, where, or which sex — the opposite of the kākā archive case, where clusters tracked the
recording channel (ARI 0.63). This is a single-protocol corpus (Koe), so that confound is
largely absent by design.
Caveats. (1) Family labels on the full corpus are stage-4 classifier
outputs (Webb 2021 taxonomy, 0.893 held-out-bird accuracy) — only the 241 projected points are
human-verified; the family toggle is therefore "classifier labels", not human labels.
(2) Cluster granularity is density-scale-dependent: at a coarser HDBSCAN sensitivity
(ms=50/mcs=100) the structure collapses to 2 mega-clusters. (3) 22.6% of syllables are
unclustered noise. (4) The explorer shows a 3,000-syllable random subsample for canvas
performance; every number above is computed on the full 19,815. Full table:
kori_syllables.csv.
Song-level view — unsupervised repertoire space
Each song as one point, described only by its composition over the 50 unsupervised
syllable clusters plus timing — no labels, no family names anywhere in the feature
space (unlike the by-bird song map above, which uses family labels for its features).
Toggle the colour to see what the space tracks: bird shows the strong individual
signature of learned song (same-bird songs clump, JSD ratio 2.12 — that's how
individual ID works), site shows the site structure that survives beyond
the individual, and sex shows what little it carries.
hover a dot · click to play song
1,496 songs · composition vectors over the 50 syllable clusters · UMAP (n=30, min_dist=0.3) · same songs as the by-bird map above, different (label-free) features
Composition battery — what does the repertoire space track? (click to expand)
Individual: JSD ratio 2.12 — songs by the same bird are twice as similar
to each other as songs by different birds. Expected for learned song, and the
confound to beat for any geographic claim.
Site beyond the individual: observed diff 0.147, permutation p ≈ 0 (200 shuffles).
Songs by different birds differ more across sites than within sites —
a between-bird, nesting-aware test, so this is structure that survives controlling for
individual identity. A candidate vocal-culture signal (repertoire composition varying by
site), NOT yet a dialect claim: sites are recording locations (6 sites, 753 birds,
individuals nested within sites), the permutation shuffles bird→site labels, and
proximity/demography/channel differences are not separately modelled.
Sex: ratio 1.09 — barely above chance; repertoire composition carries
little sex signal once bird identity is accounted for.
Earlier analysis: hand-labelled subset
Hand-labelled tutorial subset and Xeno-Canto rule-based figures (an older, different pipeline)
Classification follows the Webb et al. (2021) and Roper et al. (2018) framework.
Unlike many songbirds where "song type" is the functional unit, korimako researchers found that
syllable types are the functional units of vocal culture — korimako flexibly recombine syllables
into variable songs. Syllable boundaries defined by <15ms silence (Roper 2018). Webb et al. identified
702 syllable types across 6 sites, grouped into 20 syllable families.
Rapid repeated short elements — high amplitude peak rate
Click
3,156
24.1%
Very short impulse sounds (<40ms)
Trill
1,651
12.6%
Rapid oscillatory frequency modulation
Complex
491
3.8%
Multi-element syllables not fitting other families
Warble
429
3.3%
Frequency-modulated, tonal but complex structure
Pipe
15
0.1%
Pure tone whistles — narrow bandwidth, shared between sites (Webb et al.)
Harsh/Buzz
0
0.0%
Broadband noisy syllables (not detected)
Methodology Note
The 15ms syllable boundary follows Roper et al. (2018) — this is shorter than the 20ms used for tūī (Hill 2014),
reflecting korimako-specific vocal structure. Webb et al. validated their classification using 74 independent judges
(89.6% average match) and machine learning (96.6% accuracy via t-SNE + supervised algorithms). Our spectral
rule-based classifier is a simplification of their approach. The Koe bioacoustics software
(Fukuzawa et al. 2020) was developed specifically for this classification task.
Song Structure — Koe Dataset, Data-Driven Categories
The section above uses a spectral rule-based classifier over Xeno-Canto recordings.
This section takes a different, empirically grounded route on the Koe bellbird tutorial dataset
(Fukuzawa et al. 2020) — 2,278 songs
with 21,427 hand-labelled syllable segments. Rather than imposing categories from spectral
rules, we let the data define them: 818 syllable clips were embedded via PCA (spike-sorting style),
manually clustered by ear and eye into 10 categories, then those manual clusters seeded
DTW-barycenter templates (dynamic time warping + DBA, tslearn) that classified the
remaining 575 syllables. 816 of 818 syllables carry a category (2 excluded as noise).
This is a first-pass, single-annotator scheme
(manual clusters by Azure) meant for structural analysis, not a published taxonomy. Category names
are descriptive (Stutter, Pipe, Down…), not drawn from prior literature. "Cough + Click"
is a newly separated Cough sub-type with a reliable trailing note.
Manual cluster purity: 99.6% (240/241) against the Koe/Webb family
labels, over the 241 manually clustered points. This number carries almost no information: the manual
clusters were drawn with the family labels visible, so near-perfect purity is close to a tautology.
The figure that does carry information — seed-label agreement.
For the 575 clips the DTW template matcher labelled on its own, agreement between its assignment
and the clip's original Koe/Webb family label is 35.8% (206/575). Broken out by the category the
matcher assigned:
Assigned category
Agreement
n assigned
Stepup
7%
114
Pipe
29%
133
Flatsqueak
29%
99
Stutter
45%
67
Chortle
53%
17
Peaksqueak
58%
33
Alarmy
58%
53
Cough + Click
63%
30
Down
77%
26
Cough
100%
3
The template categories and the Koe/Webb families are different schemes, so
disagreement is not automatically error. But Stepup agrees on only 7% of the 114 clips it
was assigned, so that template is very likely matching something other than Stepup, and
those 114 labels should not be relied on. Treat every category above as provisional in proportion
to its agreement.
Method note: agreement counts
Flatspeak → Flatsqueak as a match (the same call type, spelled two
ways) and Cough + Click → Cough (Cough + Click
is a Cough sub-type). Compared as raw strings without those two equivalences the overall figure is
27.5% (158/575), which is what dtw_classify.py prints today.
Syllable Transitions
How syllables follow one another across 19,241 transitions in 2,278 songs. Rows = current syllable,
columns = next syllable; each cell is the probability of that transition. Strong diagonal =
self-repetition (birds repeat syllables in runs).
Cell shade ∝ transition probability · self-transitions on the diagonal
Common Motifs
The most frequent stereotyped syllable sequences (4-grams) across all songs. Korimako song is
built largely from repeated runs (Stutter×4, Pipe×4) and alternations (Down–Pipe–Down–Pipe).
Song Complexity — Sex Differences
Males sing longer (13.4 vs 10.6 syllables) and use more distinct syllable types
per song (4.5 vs 3.9, entropy 1.85 vs 1.56); females repeat more
(0.45 vs 0.31 of adjacent syllables identical). n = 949 male, 648 female songs.
Length-controlled: "types per song" is partly confounded with length — longer
songs have more chances to hit new types. Comparing only the first 8 syllables of each
song (matched length), males still lead on distinct types (4.2 vs 3.1) and females still
repeat more, so the difference is not merely a length artefact. It is a genuine
type-token diversity gap. (A type-token ratio gives the same direction: 0.46 male vs 0.42 female.)
Geographic Repertoires — 7 Sites
Percentage composition of each site's repertoire across the 10 syllable categories — the
beginnings of vocal dialects. BUR/LAI lean Pipe + Down; TMI favours Stutter + Alarmy;
CUV shows the most even (diverse) repertoire.
Repertoire by Sex, per Site
The same syllable-composition view, split by sex within each site. Korimako are one of the
rare songbirds where both sexes sing complex song — and Webb et al. (2021) found males and
females share only 6–26% of syllable types within a site. That sexual divergence shows up
here as clearly different category profiles: e.g. at Tāwharanui females are 68% Stutter while males
spread across Stutter, Pipe and Alarmy. Use the toggle to compare.
Per-Recording Breakdown (Xeno-Canto rule-based)
Sex & Song — is the sex signal real?
A naive classifier told male from female song at ~91% — but the same features predicted
which island a song came from at ~90%, because sex ratios differ sharply by site. So the
naive score could have been reading dialect, not sex. To separate them we trained on some
islands and tested on a completely held-out island (leave-one-site-out): a model that had
only learned "this island sounds male" would collapse to chance on a new island.
Listen: male, female & intermediate song
Full songs (not single syllables) from the hand-labelled Koe tutorial set, each scored by a model
that never saw its island. P(male) is the model's site-honest estimate that the singer is male.
What drives the score — is "intermediate" just song length?
Azure's question: are intermediate birds just otherwise sex-typical singers whose songs happen to be
longer/shorter, or are they genuinely atypical across many features? Left: the features that most push
the score toward male (+) or female (−). Right: an ablation — we drop all length/timing features
and re-score. If intermediacy were a length artifact, those birds would snap to a clear sex.
Non-binary & sex-atypical individuals
Aggregating site-honest scores by corrected individual ID (colour-band combo or site-date-code). A bird's position on the male↔female axis is a
stable individual trait, repeatability ICC = 0.67 across its own songs — so
intermediacy is not song-to-song noise. Two groups of interest: intermediate birds (reliably
mid-axis) and a sex-atypical / "trans" group (song squarely in the opposite sex category to
their ID sex).
Representative Samples
▸ Supplementary — same figures computed only on birds the models never saw in training (test split: 107 birds for repertoire figures, 37 for the sex-atypical run)
Every figure in the recompute above, recomputed on only the test-split birds — individuals
held out of all model training. If a pattern is a memorisation
artefact it weakens or vanishes here. Repertoire figures: 107 birds; sex-atypical run:
37 birds (≥10-syllable subset). Per-site counts are thin (some sites <10 birds), so treat
small wobbles as noise, not signal.
Supplementary: repertoire by site (test-split birds only)
Supplementary: sex & repertoire within each site (test-split only)
Kākā are parrots (Psittaciformes), not songbirds. They produce calls, not songs,
and the term "syllable" does not apply. This section shows the unsupervised acoustic space:
every call placed by 52 acoustic features, with no assumed categories. We show no call-type
labels, because the rule-based ones we tried (after Van Horik, Bell & Burns 2007) failed
validation. Labels return only when a classifier has been trained and validated against
human-verified examples.
Why no call types
Snicker / bark / gurgle came from a threshold-rule classifier that was never checked
against kākā calls by a human listener at scale. When we clustered the same calls
unsupervised, the clusters tracked who recorded the call (recordist ARI 0.63) far more
than any call-type structure (ARI 0.02), and listening to the "canonical" examples per category
showed they mixed unrelated call shapes. For comparison, the closely
related kea (Nestor notabilis) has 7 documented call types including the
famous "warble" play call (Schwing et al. 2012).
Per-Recording Breakdown
Total calls per recording. This counts audio and makes no call-type claim.
Unsupervised Call-Space Explorer
Where these calls come from
Two sources. Xeno-Canto archive — 47 recordings, 1,790 annotated call units,
19 recordists, 8 regions, 2008–2024: every unsupervised result on this page derives from
these recordings. Macaulay Library (staged) — 106 units from 14
recordings (1969–2016) that passed four quality gates; they are projected into the
explorer below but excluded from all cluster and dialect claims (label class:
vocalisation, species unconfirmed). (The Campbell ARU set — 53 calls, Kāpiti +
Zealandia — is the human-verified reference set that motivates the feature recipe and
the future classifier's ground truth; it is not part of the clustered corpus and is
shown separately in the reference panel below.)
Methods & assumptions — how this embedding is built (click to expand)
Pipeline. Each call unit is summarised by 52 acoustic features (13 MFCC
means, stds and delta-means + 7 spectral-contrast bands + 6 tonnetz), computed at 22.05 kHz —
the recipe validated on Fraser Campbell's ARU kākā recordings (96% leave-one-out call-type
accuracy, 95% within-skraak site accuracy on that set). Features are standardised
(z-scored per dimension), then embedded in 2D by UMAP (n_neighbours=30, min_dist=0.3,
Euclidean). Cluster colouring comes from HDBSCAN run on a 3D t-SNE embedding of the same
standardised features (min_samples=8, seed 42) — 27 clusters, 687 calls left unclustered.
The staged Macaulay subset. 201 candidate calls were detected in 17
Macaulay Library recordings (1969–2016) by the same energy-based segmenter and featurised
identically. Each candidate then passed four quality gates: not in the recording excluded
wholesale pending a listen (ML 94335961); inside the Xeno-Canto 15-nearest-neighbour
distance envelope (p95); 15-NN majority not HDBSCAN noise; and not the first segment of
its recording (tape-head announcement risk). 106 units from 14 recordings survived
and were projected into the existing embedding via UMAP transform — the Xeno-Canto
coordinates are unchanged. They carry the label class "vocalisation, species
unconfirmed": detected as vocalisations, but species identity is not ear-verifiable
from archive audio, so no call-type, cluster or dialect claims are made for them
(grey dots in the explorer; the full 201-row gate table ships alongside this page as
kaka_macaulay_staged.csv). One limitation: the channel-removed view is not available for these units — the per-recording
normalisation recipe was not recoverable bit-exactly, so only the raw-features view is
shown rather than a re-derived approximation. Channel robustness stays an open question
until a channel-robust embedder is built and tested.
The two views.Raw features preserves absolute spectral content; in a
crowd-sourced archive this makes the recording chain (microphone, gain, distance, habitat)
a dominant variance component, and clusters largely track the recordist. Channel-removed
z-normalises features within each recording (cepstral mean/variance subtraction), which
strips the recording-chain signature — and with it most discrete structure: kākā call
variation is close to a continuum in this feature space.
Assumptions. (1) That 52 summary statistics capture what matters
about a call — temporal fine-structure and sequence context are discarded. (2) That units are
correctly segmented single calls (mostly true; ~20 units are longer series). (3) That
Euclidean distance in standardised feature space corresponds to perceptual similarity —
untested. (4) UMAP/t-SNE preserve local neighbourhoods, not global geometry; distances
between far-apart points should not be over-read. (5) Clusters are
not call types: the same procedure run on raw features yields clusters that track
recordists (ARI 0.63 vs 0.02 for call-type agreement), which is why this page shows no
call-type labels.
Every call in the corpus (n = 1,896: 1,790 clustered Xeno-Canto calls + 106 staged Macaulay
units) embedded by UMAP over the same 52 acoustic
features used elsewhere on this dashboard. Click any dot to see its spectrogram and
play the call. Two views:
Raw features — the archive as recorded. Colour by unsupervised cluster
(HDBSCAN) and the 27 clusters look crisp; switch the colour to recordist and the
same map turns into a fingerprint of who recorded it — the clusters track the
recording channel more than the call type (ARI 0.63 vs 0.02). Try it: the picture
barely changes.
Channel-removed — the same calls after per-recording normalisation strips the
recording-chain signature. The channel structure vanishes, and what remains is close to a
continuum: kākā call variation grades smoothly rather than sorting into discrete
acoustic types.
The lesson: in a
heterogeneous volunteer archive, unit-level clusters are recording-channel clusters. A
dialect claim needs the composition level and the confound battery — see the
cluster viewer for the annotate-tool view of the same corpus.
view:colour:
hover a dot · click to open call
1,896 calls (1,790 XC + 106 staged Macaulay) · UMAP (n_neighbours=30, min_dist=0.3) on standardised Campbell 52-dim features · XC clusters: HDBSCAN on t-SNE (ms=8) · Macaulay units: projected, excluded from cluster claims
Campbell ARU Reference Set — human labels vs unsupervised clusters
The 53 human-verified kākā calls (Raven-annotated by Fraser Campbell, Kāpiti island +
Zealandia, single standardised ARU protocol) projected into the same call-space
embedding as the archive corpus. This set is the reason the 52-feature recipe exists
and is the project's only human-labelled kākā reference — but it was never a
validation step for the unsupervised clustering, which runs label-free
(53 calls / 3 types / 2 sites is a proof of concept, not a validation). Projecting it
here consumes nothing: the corpus, the clustering, and all claims are untouched.
Toggle the colour to compare how the human call-type labels and the
unsupervised archive clusters carve up the same calls.
hover a dot · click to open call
53 calls · projected into the archive embedding (UMAP transform, XC coordinates unchanged) · "unsupervised cluster" = 15-nearest-XC-neighbour majority HDBSCAN cluster · comparison overlay only — not part of the corpus
Behaviour–Vocalisation Correlation
Do kākā calls carry acoustic signatures of behavioural context — that is, does a call's
sound structure encode what the bird was doing when it called, beyond just the call type?
This analysis tests whether kākā vocalisations are organised by meaning, not just by sound.
This is a computational proxy for the kind of behavioural discrimination test that
Elie et al. (2025) performed with operant
conditioning on zebra finches. We can't ask kākā to discriminate calls in a lab — but we can
test whether the acoustic structure of their calls non-randomly encodes behavioural context.
Key Result: Calls from the same behaviour are acoustically more similar
MDS (Multidimensional Scaling) is a way to visualise how similar or different things are
by placing them on a 2D map. Each dot is one kākā call. The key idea: calls that sound
similar are placed close together; calls that sound different are placed far apart.
We compute the acoustic distance between every pair of calls (using 52 features — MFCCs,
spectral contrast, and tonnetz), then MDS finds the best 2D arrangement that preserves those
distances. Think of it as creating a "sound map" of the calls.
When we colour the dots by call type or behaviour, clusters tell us something: if all the
foraging calls cluster in one corner and all the flying calls in another, that means the
acoustic features are encoding behavioural context. If the colours were randomly scattered,
it would mean the calls sound the same regardless of behaviour.
What is a Mantel test?
The Mantel test asks a simple question: are calls from the same behaviour more
acoustically similar than calls from different behaviours? It compares two distance
matrices — one measuring acoustic similarity (how the calls sound) and one measuring
behavioural similarity (same vs different behaviour). A positive correlation (r > 0) means
yes, same-behaviour calls are more similar than expected by chance.
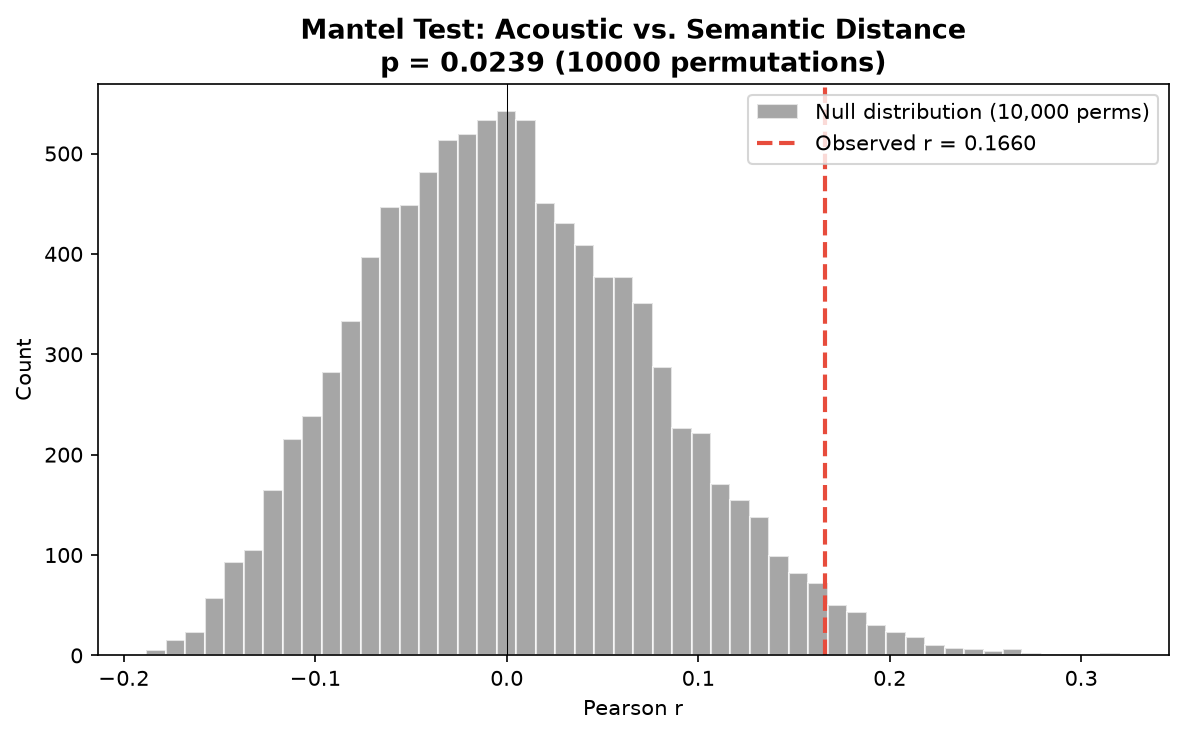
Because the test uses 10,000 random permutations to build a null distribution, the p-value
tells us the probability of seeing this pattern by chance. r = 0.166 with p = 0.024 is a
weak but statistically significant signal — the effect is real but modest, which makes
sense: call type is the strong signal (slide whistle = foraging, whistle = perching), and
within that, behavioural sub-structure is a subtler layer.
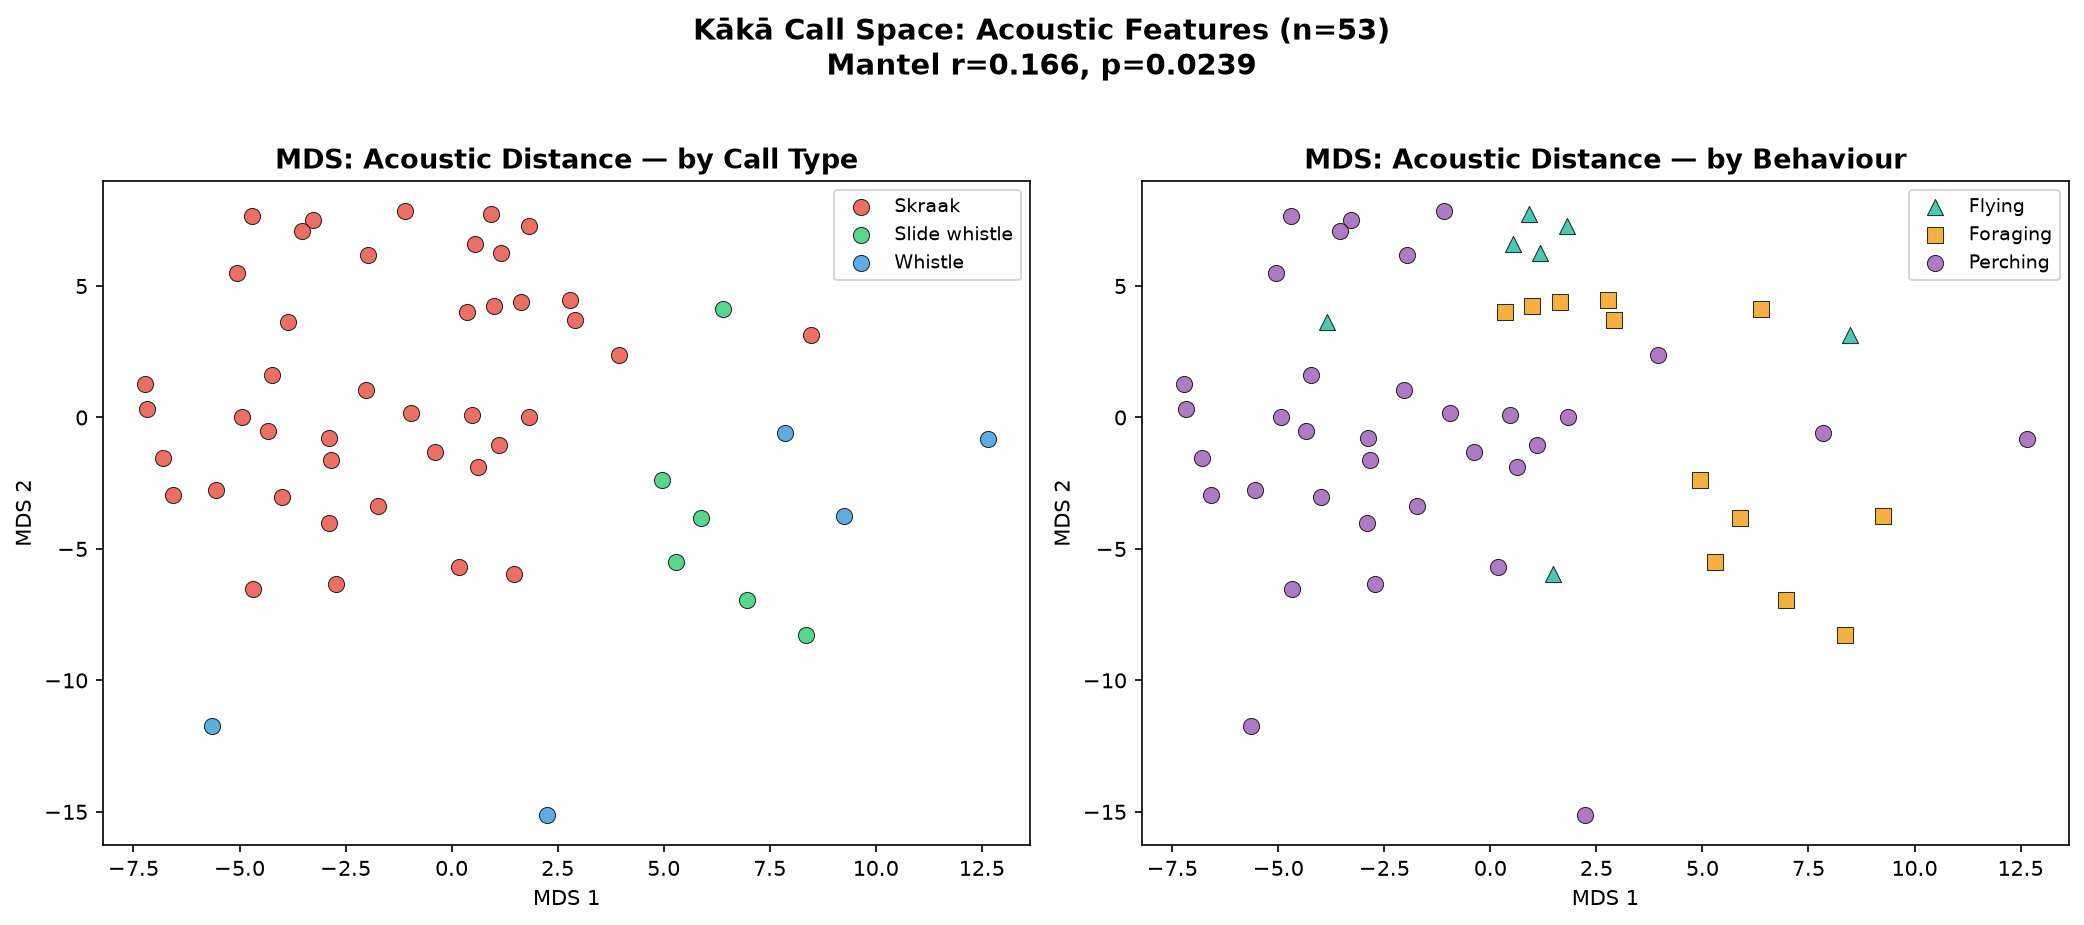
MDS: Acoustic Space Coloured by Call Type and Behaviour
Each dot is one call. Left: coloured by call type. Right: coloured by behaviour.
Call types separate clearly (skraak, whistle, slide whistle occupy different regions).
Behaviour shows weaker but visible clustering — especially within the skraak cluster,
where foraging and flying calls partially separate from perching.
Mantel Test: Null Distribution
The observed correlation (r = 0.166, red line) falls in the right tail of the null
distribution (grey bars) — meaning this degree of same-behaviour acoustic similarity
would rarely occur by chance (p = 0.024).
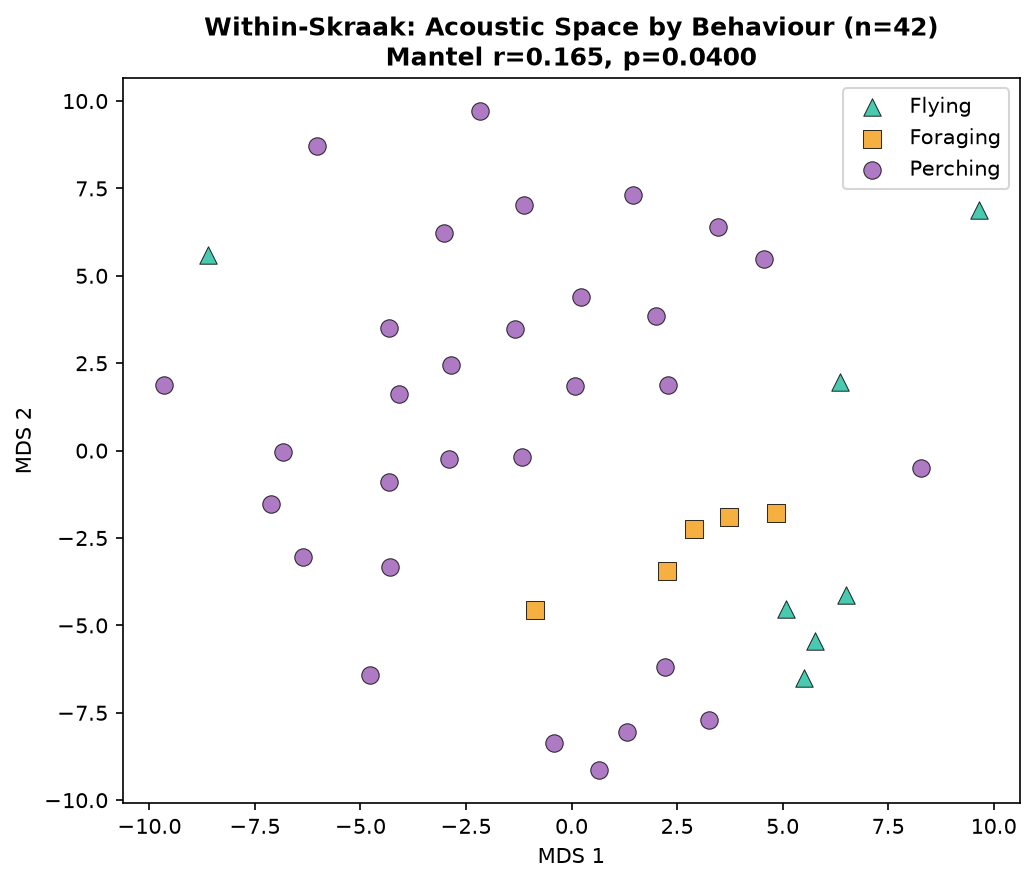
Within-Skraak MDS: Acoustic Space by Behaviour
This is the critical test. We strip away the call-type differences — only skraak calls
remain (42 of 53). If there were no behavioural signal within skraak, these dots would
be randomly scattered by behaviour. Instead, foraging (orange) and flying (teal) calls
show partial separation from perching (purple). This means skraak isn't one uniform call —
there are sub-acoustic variants that track what the bird was doing, even though
our classifier lumps them all as "skraak."
Call Type × Behaviour Cross-Tabulation
Call Type
Perching
Foraging
Flying
Pattern
Skraak
30
5
7
General-purpose — spans all behaviours
Slide whistle
0
6
0
Exclusively foraging (6/6)
Whistle
4
1
0
Mostly perching (4/5)
Slide whistle maps perfectly to foraging; whistle maps to perching; skraak spans all three
— which is why the within-skraak test is the important one.
Caveats
n = 53 calls, 3 behaviours — small sample, especially flying (7) and foraging (12)
Categories are coarse — finer context (alarm vs contact vs agonistic) might reveal stronger structure
No individual ID — controlling for individual bird could strengthen or change the signal
Acoustic proximity ≠ perception — Elie et al. tested what birds actually confuse; we're testing acoustic structure as a proxy
Data
Fraser Campbell's kākā annotations (55 annotations, 53 with valid features).
Reference: Elie et al. (2025), Science — semantic categorisation of calls in zebra finches.
The toutouwai (North Island robin, Petroica longipes) is an endemic Aotearoa
songbird — a open-ended vocal learner whose song structure remains plastic throughout life.
Unlike tūī and korimako, toutouwai are territorial and sedentary, making them ideal for
studying individual vocal signatures and dialect stability in small populations. The data
here come from the Donald dataset (Harry Donald, Shaw Lab, Victoria University of Wellington):
hand-annotated Raven selections from 28 individually named birds recorded across
multiple sessions at Zealandia Te Māra a Tāne and surrounding Wellington reserves.
Dataset Provenance
Donald dataset — Harry Donald, Shaw Lab (VUW). 28 birds, 156 annotation files,
11,879 annotated phrase selections with 73 unique phrase IDs. Recordings span
May–October 2025. Each bird has 2–9 recording sessions. Annotations are syllable/phrase-level
(not whole-song), with begin/end times, frequency bounds, and human-assigned phrase labels
using a phonetic-alphabet coding system (B, A, G, hotel, I, C, E, echo, beta, india, etc.).
Each bar shows the phrase repertoire of one individually named bird. Phrase B (16.9%)
is the most common across the population, but individual repertoires vary —
Goose has just 9 phrase types while Rowan and Bazooka have 25. This inter-individual
variation is the basis for vocal individual recognition.
Phrase repertoire overlap between birds, measured by Jaccard similarity. High similarity
(e.g. Charlie ↔ Karl: J=0.765) suggests shared local dialect; low similarity
(e.g. Goose ↔ Tegan: J=0.200) suggests divergent repertoires — potentially due to
geographic isolation, age, or individual specialisation.
Individual Bird Recognition
The Donald dataset's structure — named individuals with multiple recording sessions —
opens the possibility of training a CNN classifier to identify individual birds from
their vocalisations alone. If birds have individually distinctive phrase repertoires
(as the Jaccard analysis suggests), a classifier could learn to say "that's Arthur" from
a new recording. This would enable tracking birds across months and years without visual
identification — a powerful tool for monitoring translocated populations at sites like
Zealandia. Status: Future work — the current dataset has 2–9 sessions per bird,
which may be sufficient for proof-of-concept but would benefit from more recordings
across longer time spans.
Geographic Analysis — Regional Vocal Variation
Do birds from different regions sing differently? We mapped syllable repertoires across
Aotearoa for tūī and korimako. The results suggest regional variation: Auckland tūī
are the most vocally diverse and Southland birds the most monotone. For kākā the question
is still open.
1,607 geotagged recordings from Xeno-Canto, coloured by species. Click markers for recording details.
Use the filters to isolate species of interest.
All Species
Tūī
Korimako
Kākā
Kea
Morepork
● Tūī ·
● Korimako ·
● Kākā ·
● Kea ·
● Other species
Tūī — Regional Syllable Repertoires
Syllable type proportions across regions, using the species-specific classifiers.
Tūī sorted by vocal diversity (Shannon entropy).
Tūī Syllable Mix by Region
Stacked bars: syllable type proportions per region · 113 geotagged tūī recordings · computed before the sample doubled to 232; refresh pending
Regional Diversity Index
Shannon entropy of syllable types per region — higher = more diverse repertoire.
Trill Gradient
Tūī trill usage varies regionally — Northland and Marlborough tūī show the most trill activity,
while Waikato and Tasman/Nelson birds trill less frequently.
Kākā — Geographic Coverage
We cannot yet say whether kākā calls differ by region. In this corpus recordist and region are
inseparable (repertoire-distance ratios: region 1.46 ≈ recordist 1.43 ≈ year 1.42), and there
are no validated call types to compare. Kākā calls from 8 regions across both islands are in
the corpus; whether geographic structure exists needs human-verified call types first.
Where the recordings come from
47 recordings · 1,790 call units · 8 regions (Waikato 22, Stewart Island 11,
Wellington/Manawatū 5, Nelson/Tasman 3, Auckland 2, Northland 2, Kāpiti Island 1,
other/unresolved 1) · 2008–2024 · 19 recordists. Explore per-call geography in the
Vocalisations tab's unsupervised explorer.
Korimako — Regional Variation
Korimako Syllable Mix by Region
46 geotagged korimako recordings across 12 regions
Dataset Overview
Recording Quality
Recording Type
Top 20 Species by Recording Count
Full Species Inventory
#
Species
Recs
Q:A
Q:B
Songs
Calls
Top Regions
Methodology
How We Did This
Data
We queried the Xeno-Canto API v3 for all recordings geotagged to New Zealand, yielding 3,096 recordings across 177 species
(including soundscapes and unidentified). After filtering, the clean dataset contains 2,244 identified bird recordings across 175 species.
Quality ratings: A (930), B (1,669), C (324), D (123), E (9)
Recording types: 1,049 songs, 1,178 calls, 869 other
Date range spans several decades of field recording
Four further datasets, each used for one species or one check:
Koe korimako corpus (Fukuzawa et al. 2020): hand-annotated songs from banded birds. Trains and tests the korimako models.
Donald toutouwai dataset (Harry Donald, Shaw Lab, VUW): 28 named birds, 11,879 annotated phrase selections.
Campbell kākā reference set (Fraser Campbell, Shaw Lab, VUW): 53 human-verified calls from Kāpiti and Zealandia.
Macaulay Library: korimako recordings used to try the models on unlabelled field audio; kākā units staged into the explorer but excluded from all claims.
Tūī: rule-based syllable pipeline
Replicating Hill & Ji (2014) as closely as possible given the different recording conditions:
Recording quality varies: XC recordings range from professional to phone-quality; Hill used a consistent Marantz PMD620 + Sennheiser ME67 setup
No "harsh" or "other" categories: Hill's manual classification included these; our rule-based system forces syllables into the five automated types
Threshold sensitivity: The 2kHz low-frequency cutoff may capture environmental noise and non-vocal sounds
Single-site vs multi-site: Hill's results come from one population (Tāwharanui); ours span the country, so inter-population variation is confounded with methodological differences
Korimako: learned pipeline
Segmentation: TweetyNet v2, a convolutional network that finds syllable boundaries in the spectrogram (architecture family from Cohen et al. 2022). F1 = 0.902 at 50 ms on a 165-song held-out test split in which no bird appears in both training and test.
Syllable typing: a family classifier trained on the Koe hand-labelled corpus, 0.893 test accuracy across 24 families plus UNKNOWN.
Sex from repertoire: 5-fold cross-validated, 0.940 CV accuracy on 454 birds (≥10-syllable subset), 0.892 on the 107 birds held out of all training.
Site / dialect from repertoire: repertoire composition identifies home site.
Individual identification: closed-set, 77 birds, top-1 55% / top-5 80%. Reliable per-bird estimates need about 6–8 songs, and the corpus is thin there (median 2 songs per bird).
Full-corpus figures are computed on 1,065 birds / 21,463 syllables, and separately on the 107-bird
test split never seen in training. Both are on the Korimako panel with per-figure n.
Kākā: unsupervised call space
Each call is summarised by 52 acoustic features and embedded with UMAP; clusters come from HDBSCAN.
No call types are assigned. The full recipe and its assumptions are in the methods fold on the Kākā panel.
Does it work on new field recordings?
The korimako numbers above all come from the Koe corpus, recorded under one protocol and annotated by
its original researchers. To see what happens on arbitrary field audio, we ran the segmenter and the family
classifier, with no retraining, on Macaulay Library korimako recordings they had never seen.
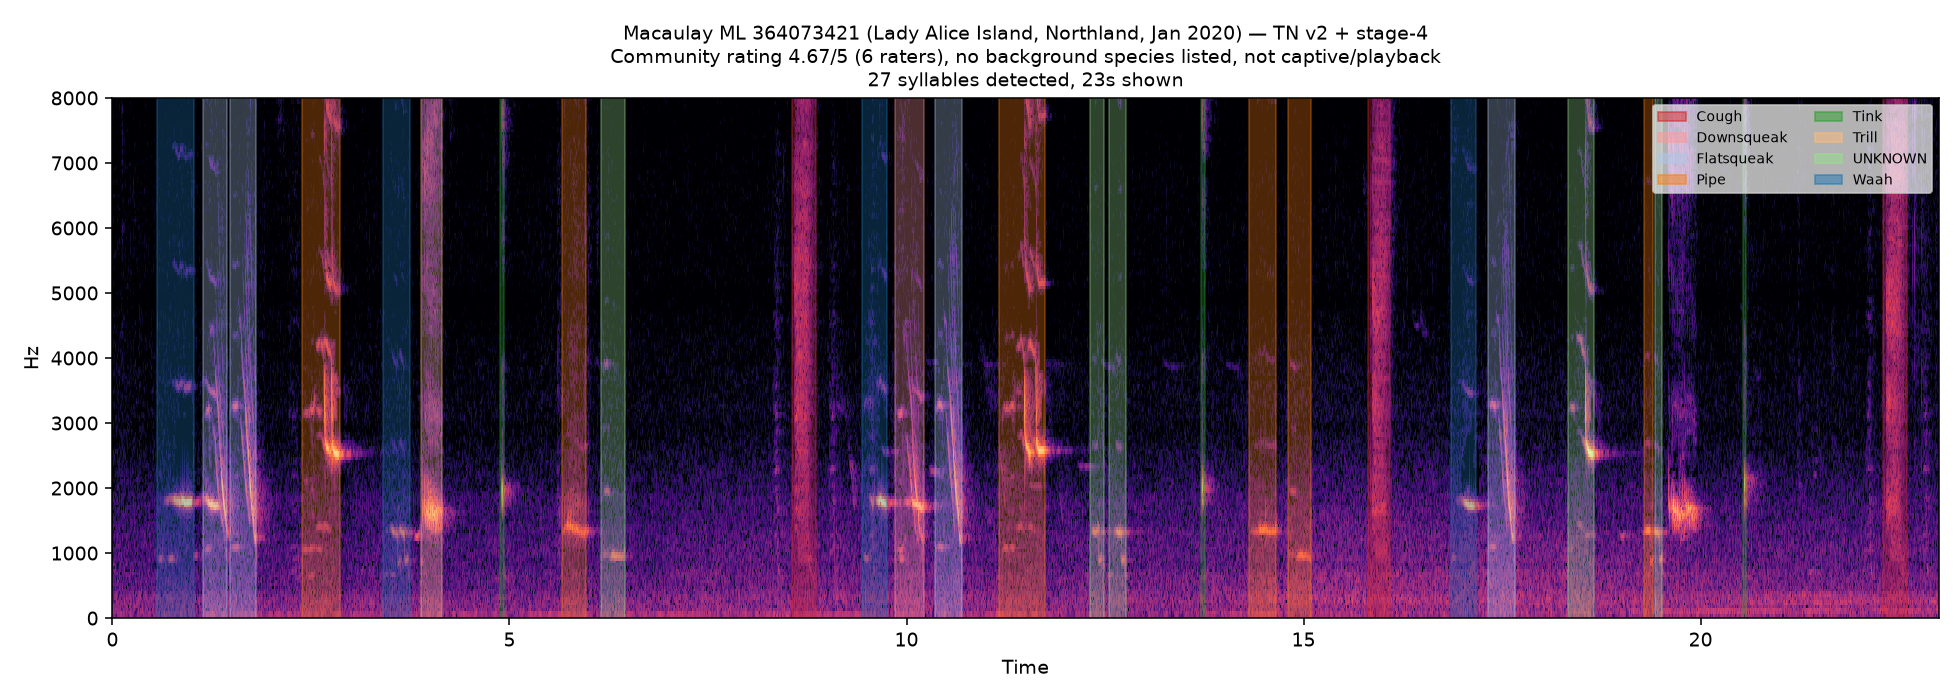
It runs, and the output is plausible. On a clean 25 s recording (Nelson Lakes NP, Feb 2023) it found 48 syllables across 13 families with sensible boundaries. There is no ground truth for that recording, so this shows the pipeline runs end to end. It does not show the output is correct.
Confidence falls with recording quality. Across 607 usable recordings, the mean fraction of confident frames (p ≥ 0.6) rises 0.089 → 0.151 → 0.188 from the low to medium to high signal-to-noise tertile (Spearman r = 0.508, p < 0.0001).
A quality floor helps but does not fix it. Near-miss frames (probability 0.3–0.6) show no strong quality trend, so some real vocalisation is missed even in clean recordings.
The worked example (ML 364073421, Lady Alice Island, Northland, January 2020; rated 4.67/5 by 6 independent listeners) was chosen by Macaulay community rating, not by an acoustic score:
annotated spectrogram and
source audio.
Sample Size Adequacy — Entropy Rarefaction
To verify our sample sizes are sufficient, we computed Shannon entropy rarefaction curves —
subsampling recordings at each N (100 iterations) and measuring whether the entropy estimate stabilises.
A plateau means adding more recordings would not substantially change the proportional distribution of vocalisation types.
Entropy vs Recording Count
Shaded bands: ±1 SD from 100 random subsamples at each N · All three species plateau well before their full sample size
All three species reach stable entropy by ~15–20 recordings. Current sample sizes (tūī 232, korimako 94,
kākā 47) are well past that. This supports the proportional distribution of vocalisation types,
though not the detection of rare types. Note: the chart above was computed on the earlier, smaller
samples (116 / 40 / 25) and has not been rebuilt.
Inclusion threshold. On this basis we set a minimum of 20 A-quality recordings as the criterion for
reporting a species' proportional repertoire. This is the point by which all three species' entropy curves have flattened
to within ±1 SD of their full-sample value, so a species meeting it can be characterised without the estimate being
dominated by sampling noise. All three focal species clear the bar. The threshold governs
only the proportional-distribution claims; detecting rare vocalisation types (present at <5% prevalence)
requires substantially larger samples and is treated as out of scope here.
Open questions
Annotation ceiling. Every segmentation score measures agreement with one person's annotations. How closely two annotators agree with each other was unmeasured as of August 2026, so we cannot say how much headroom is left.
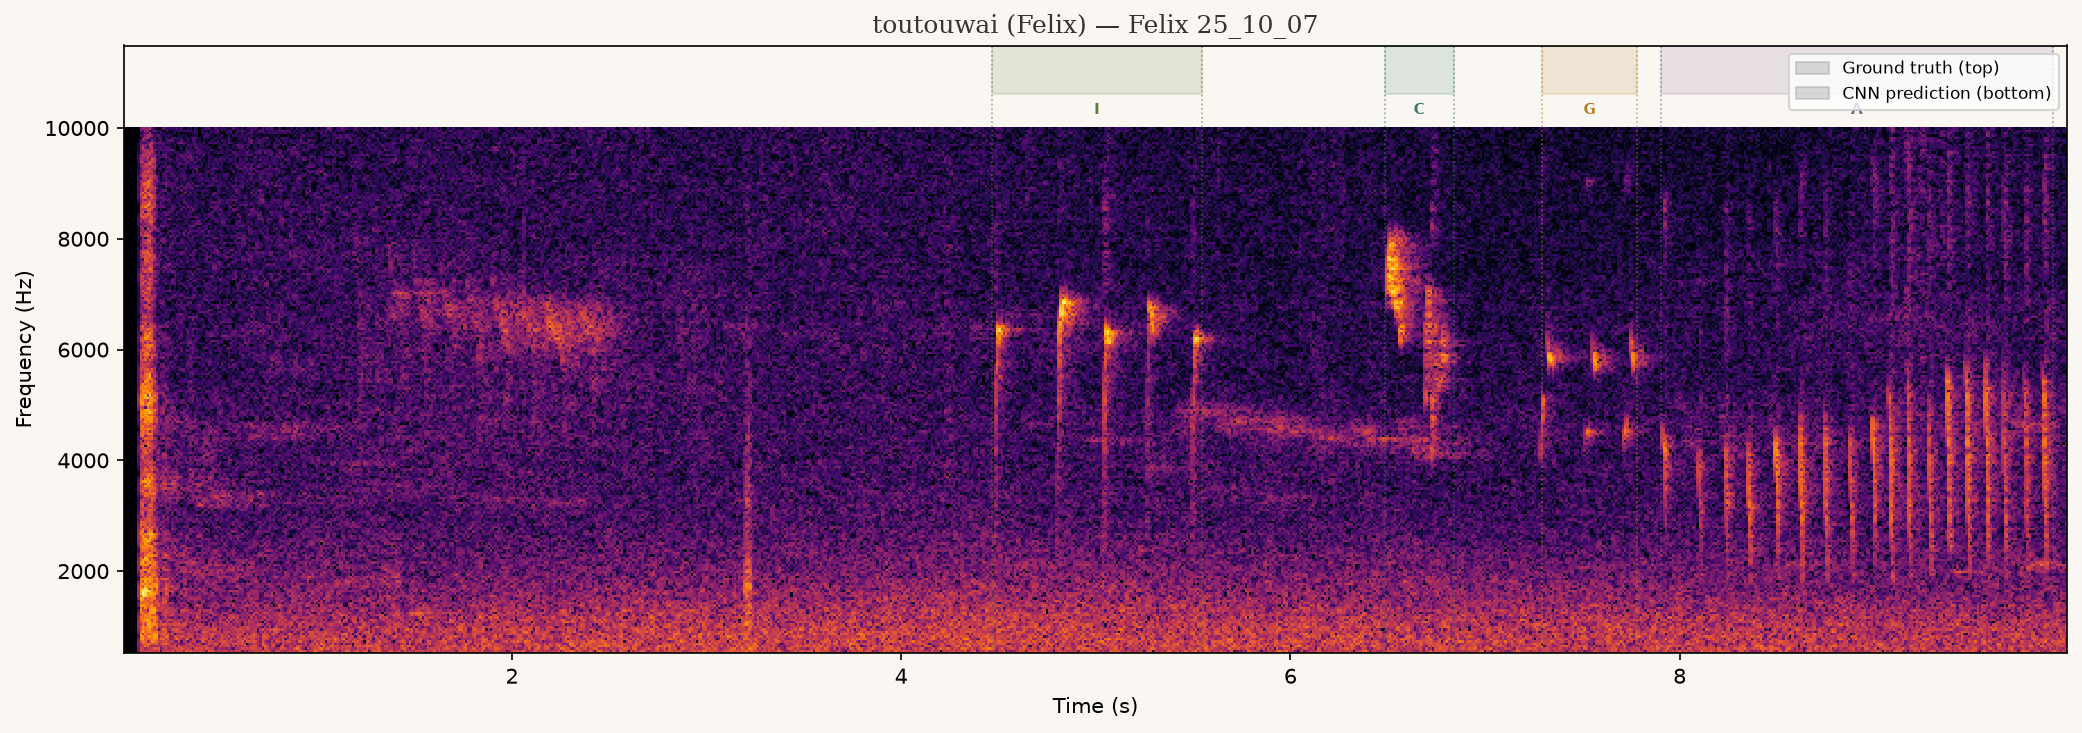
Toutouwai segmentation. The CNN has not been validly evaluated on toutouwai. On the one weak test that exists (13 files, July 2026) it scored F1 0.262, behind both classical baselines (FIR 0.306, spectral flux 0.329).
Data augmentation. Two runs disagreed on whether it helps and neither was clean (as of August 2026).
Noise in the Koe corpus. We have not checked whether noisy Koe recordings affect the full-corpus figures.
Kākā call types and dialects. Both wait on a classifier validated against human-verified calls.
Earlier results, corrections and withdrawn claims are in the Process tab.
Reproducibility
The full analysis pipeline is available at github.com/cyborg-garden/open-science.
The Python venv uses librosa for audio analysis and scikit-learn for clustering. All Xeno-Canto recordings are publicly available via their API.
Who made this
This dashboard was compiled by Matilde, an agentic open-science research assistant.
Literature Review
The tūī vocal repertoire has been studied primarily by S.D. Hill and colleagues at Massey University.
Their work at Tāwharanui Regional Park established the foundational syllable categorisation scheme we replicate here.
All citations below have been verified against Crossref.
Which framework, per species
The tūī figures use Hill & Ji's rule-based syllable categories. The korimako
figures use a classifier trained on the Fukuzawa et al. (2020) Koe hand-labelled corpus (24 families,
0.893 test accuracy). Kākā calls carry no automated labels; Van Horik (2007) and Vaishnav (2026)
are cited for the ethology and for our annotation tools.
Syllable Categorisation Replicated
Hill & Ji (2014) established six syllable categories for tūī song at Tāwharanui: low-frequency, high-frequency, harmonic,
trill, RMNR, and harsh/other. Harmonic syllables were the most common (~15%). Our automated pipeline captures five of six categories
but finds different proportions: RMNR dominates at 64.7% and harmonic is 13.8%.
Hill et al. (2017) showed that more complex tūī songs elicit stronger aggressive responses from territorial males —
"fighting talk." This motivates the repertoire analysis: if song complexity varies geographically,
it may signal different competitive environments.
Hill et al. (2015) documented microgeographic variation in tūī song within the Tāwharanui population. Our dataset —
spanning the entire country — enables a macro-scale version of this analysis, comparing repertoires across Auckland, Wellington,
Southland, and beyond.
Hill, S.D. et al. (2015). NZ J. Ecol., 39(2), 261-269 ✓
Chatham Island vs Mainland
Hill et al. (2013) compared tūī vocalisations between Chatham Island and mainland populations, finding differences
attributable to isolation and smaller population size. Xeno-Canto data includes offshore recordings that could extend this work.
Hill, S.D. et al. (2013). Notornis, 60, 222-229 ✓
Korimako (Bellbird) — Anthornis melanura
Korimako syllable classification follows the Massey University group (Brunton, Roper, Webb, Fukuzawa).
Their framework treats syllable types, not song types, as the functional units of vocal culture.
Citations verified against Crossref.
Sexually Distinct Song Cultures Framework
Webb et al. (2021) classified 20,700 syllables (702 types) across a six-island korimako metapopulation,
showing males and females have distinct song cultures sharing only 6–26% of syllable types within a site.
This is the classification framework and the sex-difference result our song-structure analysis builds on.
Roper et al. (2018) studied developmental changes in song production in free-living male and female
bellbirds. We adopt their <15ms silence syllable boundary — shorter than the tūī boundary — reflecting
korimako-specific vocal structure.
Koe Classification Software Tool + dataset + current korimako typing scheme
Fukuzawa et al. (2020) introduced Koe, web-based software for classifying acoustic units, demonstrated
on 21,500 korimako syllables. Our data-driven song-structure analysis uses the Koe tutorial dataset
(2,278 songs, 21,427 hand-labelled segments) as its ground-truth source. The 24-family label scheme
from this dataset is what our family classifier predicts for every korimako syllable (0.893 test accuracy).
Kākā are parrots, not songbirds — they produce calls, not songs. Two frameworks are relevant.
Kākā Vocal Ethology Call types
Van Horik, Bell & Burns (2007) identified five distinctive kākā call types through 500 hours of field
observation and spectrographic analysis (snicker, bark, gurgle, shraak, shraak-woo). We cite it for the
ethology. A rule classifier we built on this scheme failed validation, so no call on this page is
labelled with these types.
Partial Nocturnality & Call Repertoire Current scheme
Vaishnav, Shaw & Burns (2026) describe kākā vocal behaviour including a five-call-type scheme
(whistle, screech, long call, croak, warble). Our annotation and template-matching tools use this newer
scheme, with audio templates provided by the lead author (Burns lab, VUW).
Temporal analysis: How has the XC archive's tūī song changed over decades? Do more recent recordings capture different repertoires? Seasonal and temporal patterns will be explored in a future species-specific analysis.
Tūī template matching: Apply the PCA → manual-cluster → DTW-template approach used on the
korimako hand-labelled subset to tūī, and extend to additional species (tīeke, kōkako) and datasets (AviaNZ kiwi).
Kākā call types: Train a classifier against human-verified calls before any labels return.
This project publishes its mistakes. The other tabs show where things stand now. This tab is the
record of how we got there: each claim we corrected or withdrew, newest first, with the note as it
was first published.
The original notes were written in place on the page, so "above" and "below"
inside them refer to an earlier layout. Nothing in them has been reworded.
3 September 2026
Kākā call-type labels withdrawn
The dashboard used to sort kākā calls into snicker, bark and gurgle with a rule-based classifier built on Van Horik, Bell & Burns (2007). Those labels were never checked by a human listener at scale. Unsupervised clusters of the same calls tracked who made the recording (ARI 0.63) far more than call type (ARI 0.02), and the "canonical" examples for each category mixed unrelated call shapes.
We removed the category charts, the sample cards sorted by category, and a regional "forest dialects" comparison built on them. The same day, 106 Macaulay Library units were staged into the explorer, excluded from all claims.
Original notes
Kākā are parrots (Psittaciformes), not songbirds. They produce calls, not songs.
The term "syllable" is inappropriate for their vocalisations. The rule-based call-type
categories previously shown here (Van Horik, Bell & Burns 2007) were
withdrawn on 2026-09-03: they failed validation against unsupervised clustering and
human-listened examples, and displaying them as if established was misleading. What this
section now shows is the unsupervised acoustic space — every call embedded by 52
acoustic features, with no assumed categories. Call-type labelling returns only when a
classifier has been trained and validated against human-verified examples.
Why categories were withdrawn
Snicker / bark / gurgle were the output of a threshold-rule classifier, never verified
against kākā calls by a human listener at scale. When we clustered the same calls
unsupervised, the clusters tracked who recorded the call (recordist ARI 0.63) far more
than any call-type structure (ARI 0.02) — and listening to "canonical" examples per category
showed they mixed unrelated call shapes. A category system that fails both checks should not
be displayed as established knowledge, so it is gone. For comparison, the closely
related kea (Nestor notabilis) has 7 documented call types including the
famous "warble" play call (Schwing et al. 2012).
Sample cards by rule category (snicker / bark / gurgle) were removed with the categories
themselves — the labels were unreliable, so cards organised by them were misleading.
To see and hear individual calls, use the Unsupervised Call-Space Explorer below:
every one of the 1,790 calls is clickable there, with its spectrogram and audio.
The earlier "forest dialects" comparison on this page was removed: the regional call-type
profiles it showed were built from rule-classifier categories that failed validation, and the
confound battery showed recordist and region were inseparable in this corpus (repertoire-distance
ratios: region 1.46 ≈ recordist 1.43 ≈ year 1.42). What we can say honestly: kākā calls from
8 regions across both islands exist in the corpus, and whether geographic structure exists
is an open question that needs human-verified call types first.
25 August 2026
Two example recordings misled us
Trying the korimako models on unlabelled Macaulay recordings, we first compared one recording per quality tier and saw the opposite of the real trend: the low-quality example produced 8× more segments. That recording was simply more vocally active. The trend across 607 recordings is the result that holds.
Separately, a recording that our loudness-based quality score rated "high quality" could not be confirmed as clean bellbird song. Example recordings are now chosen by Macaulay's community ratings.
Original notes
25 August 2026 — what happens when the pipeline meets real, unlabelled audio
Every number above comes from the Koe corpus — recordings collected under
a consistent protocol and hand-annotated by the original researchers. That is not the same question
as does this pipeline work on an arbitrary field recording with no ground truth, which is
the situation anyone actually deploying this would face. We ran TN v2 + the stage-4 classifier, cold,
on Macaulay Library korimako recordings never touched by training or evaluation, to find out.
It runs, and produces plausible output. On a clean 25s field
recording (Nelson Lakes NP, Feb 2023), the pipeline found 48 syllables across 13 stage-4 families with
sensible temporal boundaries and no degeneration to noise or a single repeated label. There is no
ground truth for this recording, so this cannot be scored as accurate — it demonstrates the pipeline
runs end-to-end on real audio, not that its output is correct. That distinction
matters and we are not blurring it.
Detection confidence measurably degrades with recording quality — but
only visible at scale, not from single examples. We scored 836 Macaulay bellbird recordings by an
SNR proxy (20th-vs-95th percentile energy ratio in the vocal band; the same idea as Xeno-Canto's A–E
quality field, computed directly since Macaulay has no such rating), then ran the segmentation model's
raw frame-level detection probability on the 607 usable recordings (excluding near-silent and
near-continuous-noise clips). Result: mean confident-frame fraction (p≥0.6, the validation-tuned
threshold) rises 0.089 → 0.151 → 0.188 from the low to medium to high SNR tertile
(Spearman r=0.508, p<0.0001, n=607). Lower-quality recordings genuinely produce less confident
segmentation.
A single-example comparison across quality tiers was actively
misleading, and we are keeping the record of that rather than quietly fixing it. Our first attempt
picked one representative recording per SNR tertile and found the opposite pattern — the
low-SNR example produced 8× more segments than the high-SNR one, which we initially (wrongly)
read as the model hallucinating on noise. Checking the actual frame-level detection probabilities
showed that recording was simply more vocally active, and a separate medium-quality example had a
genuine, undetected 7-second song passage that the single-example view made easy to miss entirely.
The population-level result above (n=607) is what actually holds; the anecdote did not generalise,
and would have been wrong to publish as the finding. This is the reason we do not report
few-example demonstrations as evidence of a trend on this page without also running the trend at
scale.
Practical implication: an SNR floor before running the pipeline on new
field recordings would reduce, but not eliminate, low-confidence output — near-miss frames
(probability 0.3–0.6, likely real vocalisation the model is unsure about) do not show a strong
quality trend on their own, so some genuine misses will occur even in clean recordings. We have not
yet checked whether any Koe corpus recordings are similarly noisy in a way that could affect the
full-corpus figures above; that is open follow-up work, not yet done.
Addendum (25 August 2026) — the SNR proxy also failed on a single example, and here is the fix
Separately from the population-level analysis above, we picked one
SNR-proxy-scored "high quality" recording (Akaroa foreshore, a populated harbour town) to show as an
illustrative example. The pipeline confidently (mean confidence 0.89) segmented and labelled ~32
loud, regular transients as bellbird syllable types. On inspection this recording could not be
confirmed as clean, unambiguous bellbird song — the SNR proxy measures loudness and regularity
in a frequency band, not is this actually a bird, and a loud non-vocal or ambiguous sound in
a populated area can score "high quality" under that metric just as easily as a clean bird call can.
We could not resolve from the spectrogram or spectral statistics alone whether those transients were
real bellbird calls; a listen suggested "maybe a weird, cicada-like call" — genuinely
ambiguous, not resolved either way, and we are not asserting a verdict on that specific recording.
The fix: use independent human verification, not an acoustic proxy, to
select the illustrative example. Macaulay Library records a community rating (0–5, from
independent listeners), a background-species field, and playback/captive flags — a real
provenance signal our SNR proxy never had access to. Filtering the 980 Macaulay korimako recordings to
rating ≥4.0 from ≥3 raters, no listed background species, not captive, playback not used, left
46 candidates. The current illustrative example on this page (ML 364073421, Lady Alice Island,
Northland, January 2020; rated 4.67/5 by 6 independent raters) is drawn from that filtered set:
annotated
spectrogram and source
audio are both published so a reader can check the labels against the sound directly rather than
take our word for it.
What this changes and what it doesn't: the population-level result (n=607,
confidence rising with SNR, Spearman r=0.508) is unaffected — it never depended on any single
recording's identity being correct. Only the single illustrative example changed. We are keeping this
addendum rather than quietly swapping the figure, because "our first quality metric let an ambiguous
recording through as a headline example" is itself informative about the limits of acoustic-only
quality proxies for field data with no ground truth.
24 August 2026
Korimako moved to a learned pipeline
Korimako moved from rule-based categories to TweetyNet v2 segmentation (F1 0.902 on a test split with no shared birds) and a family classifier (0.893). The 0.902 replaces the 0.8577 in the entry below, which came from a split with the same birds in training and test. The two numbers are not directly comparable.
Original notes
Current pipeline (24 August 2026) — read this one first
Everything below this box is the record of how we got here, kept
unedited per the kaupapa of this project. But it is now history, not the live pipeline. If you
read one section on this page, read this one — it names what actually generated tonight's korimako
figures and manifold.
The current korimako pipeline, end to end:
Segmentation: TweetyNet v2 (CNN), F1 = 0.902 on a held-out test split — this
supersedes the 0.8577 result below, which was measured on a split with bird-level leakage between
train/val/test (see the 5 August correction). The new number is not directly comparable to the old
one; treat 0.902 as the current best estimate, not confirmation the old number was "wrong by
exactly this much."
Syllable typing: a stage-4 family classifier trained on the Koe hand-labelled corpus
(Fukuzawa et al. 2020), 0.893 test accuracy across 24 families plus UNKNOWN — this replaces
the rule-based 5-category Hill & Ji scheme for korimako specifically (that scheme was built for
tūī and is retained for tūī, see below).
Sex from repertoire: 5-fold cross-validated, 0.940 CV accuracy on 454 birds
(≥10-syllable subset), 0.892 on the 107 birds held out of all training.
Site / dialect from repertoire: repertoire composition identifies home site.
Individual identification: closed-set, 77 birds, top-1 55% / top-5 80%; reliable per-bird
estimates need ≈6–8 songs, and the corpus is thin there (median 2 songs/bird) — stated plainly on
the korimako panel rather than hidden.
The tūī analysis below (rule-based Hill & Ji categories, CNN
segmentation only, no typing model) is not superseded — it is a separate species with its own
pipeline, which is why the acoustic manifold now shows a korimako example (TN v2 + stage-4) front and
centre and keeps the tūī recordings as a labelled "legacy rule-based" option in the dropdown, not
because the tūī work is wrong, but because it is a different, older method applied to a different
bird. Kākā uses a third, call-based approach (analysed unsupervised; its rule-based categories were withdrawn
after failed validation) that has no sequence
grammar and is out of scope for the sequence-based methods below.
Full-corpus figures (repertoire, sex, site, atypical individuals) recompute on
1,065 birds / 21,463 syllables for the main tier, and separately on the 107-bird test split never
seen in training, for the honest-tier check. Both are on the live korimako panel with per-figure
n stated.
Which framework is live, per species (24 August 2026)
All citations below remain valid — they are the ground-truth sources and
conceptual frameworks this project draws on. What has changed is which one drives the current
korimako figures: Hill & Ji's five/six-category rule-based scheme is the live method for
tūī, but for korimako it has been superseded by a stage-4 classifier trained directly on
the Fukuzawa et al. (2020) Koe hand-labelled corpus (24 families, 0.893 test accuracy) — see the
Methodology tab's "Current pipeline" note. Kākā uses the Van Horik (2007) / Vaishnav (2026) call-type
frameworks, unchanged.
5 August 2026
Segmentation headline replaced, with its limits
The page had been showing F1 = 0.784 for korimako segmentation while also saying that number did not reproduce. It was replaced with a held-out result: CNN 0.8577 against FIR envelope 0.7212, both scored the same way. Its limits: 15 test files, one site, one week, and the same birds on both sides of the split. We also listed five things we did not know at that date.
An audit the same day checked whether 3,156 appearing twice on the page (total recordings, and korimako click syllables) was a copy-paste error. It is a coincidence; both are correct.
Original correction
Correction (5 August 2026) — new headline result, and its limits
This page has shown F1=0.784 as the bellbird segmentation result while
also stating, three paragraphs below, that the artifact behind 0.784 no longer exists and the number does
not reproduce. That is not a tenable thing to keep publishing. Meanwhile the best-provenanced comparison
we have has sat unpublished on a lab machine since 29 July. Both halves of that are corrected here. The
0.784 discussion below is retained unedited — it is the record of how we got here.
The current result: CNN F1 = 0.8577, FIR envelope F1 = 0.7212
(Δ = +0.137) on split 88513a3aaa91. Unlike 0.784, this one is a held-out estimate and
both arms were scored the same way. The CNN here is the SpecAugment-trained model — we name
the model because a later run appeared to show augmentation hurting, and that run turned out to be
invalid (it resampled the audio to a rate the model was never trained at, which cost 0.13 F1 on its own).
Whether augmentation helps is currently unknown; see “What we do not yet know”.
Method
Threshold
P
R
F1
CNN (TweetyNet-style)
0.45
0.846
0.870
0.8577
FIR envelope
0.70
0.882
0.610
0.7212
15 held-out test files, 246 ground-truth segments. One matching
criterion for both arms — IoU ≥ 0.3 OR overlap ≥ 0.5, greedy by detected length.
Both operating thresholds chosen by argmax F1 on a separate validation split, not on test.
Paired sign test over the 15 test files: 12 favour the CNN, 2 favour FIR, 1 tie,
p = 0.035 two-sided. (The value recorded in the source artifact, 0.0176, is one-sided; we publish
the two-sided figure.) Source: rescore_final_results.json, 29 July 2026.
Now the part that matters more than the number. This is not evidence that
the CNN generalises, and we are not claiming that it does.
n = 15 test files. Every claim on this page about segmentation rests on fifteen recordings.
One site, one week. All 60 files in this split come from a single site (CUV), recorded across
five days of November 2016. There is no second site and no second season.
Bird-level leakage in both directions. The split is file-disjoint — no recording appears
in two partitions — but it is not bird-disjoint. Of the 12 distinct birds in the test set,
4 also appear in training (AMH015, AMH036, BAE042, WHW021) and 6 also appear in validation
(BAE037, BAE042, BAE047, DHB008, DHB016, WHW021). In one case the annotator's own filename says so:
AMH015_01_M…TrumpetSongSameBirdAsTr014Harmonics.wav is in train and
AMH015_02_M… — same bird, same song type — is in test.
The operating point was selected on birds present in the test set. This follows from the two
facts above and is the one that does the most damage. The methodology note "threshold tuned on
validation, not test" is true at the file level and false at the level that matters, because half
the test birds are validation birds.
So read 0.8577 as within-individual, within-site, within-week segmentation
performance. That is a real quantity and a reasonable place to be after five weeks. It is not the
quantity a reader will assume from "CNN F1 = 0.858", and it does not support "this method works on New
Zealand birdsong." A re-split grouped by bird rather than by file is the next measurement, and we expect
the number to fall; the size of that fall is the finding, not a failure.
What we did not yet know, as of 5 August
What we do not yet know (5 August 2026)
Five open questions that bear directly on everything above. None of these has
an answer yet, and we would rather say so here than have a reader discover it. Per the kaupapa this project
works under, a finding is a baton and everything the next runner needs to succeed — which
means the unresolved parts are part of the finding, not an embarrassment to be tidied away.
Whether data augmentation helps or hurts — direction unresolved. A 29 July run found
augmentation improved F1 (+0.033); a 3 August run found it hurt (−0.078). The two runs are
not comparable: the 3 August run's FIR baseline collapsed from 0.721 to 0.424 because the
registered baseline was never loaded, and its "augmented" arm reused a borrowed checkpoint rather than
retraining. Neither run supersedes the other. We therefore publish no augmentation qualifier on the
number above, in either direction, until a clean ablation exists.
How WhisperSeg compares — currently unmeasurable. WhisperSeg is being evaluated in
parallel, but its scoring counts a prediction correct on any overlap with ground truth, while the
CNN and FIR numbers require IoU ≥ 0.3 or 50% overlap. A more permissive matcher produces
a higher F1 for free. No WhisperSeg-vs-CNN comparison appears on this page and none should be quoted
from elsewhere until all three methods are re-scored through the single canonical matcher. This is
the same error class we publicly withdrew in July; we are declining to make it a third time.
The annotation ceiling — unmeasured, and it bounds every number here. Every F1 on this
page measures agreement with one person's annotations, treated as truth. But where a syllable
starts is genuinely ambiguous, and two experienced annotators will disagree. If human annotators agree
with each other at F1 ≈ 0.85, then 0.8577 is at the ceiling and further tuning is fitting one
annotator's habits. If they agree at 0.97, there is real headroom. We currently cannot tell which
world we are in, which makes this the highest-value unmeasured quantity in the project.
How much of the result survives a bird-grouped split. See the correction above: the current
split is file-disjoint but not bird- or site-disjoint. Until the re-split is run, the reported figure
cannot be read as generalisation to unseen birds, let alone unseen sites.
Why the label set was cut from 41 families to 14. The Koe taxonomy carries 41 label families;
the trainers filter to 14 by a minimum-count threshold. That threshold is not recorded in any
provenance block, so we cannot currently state what fraction of segments the 27 dropped families
represent, or how the result moves at a different cut. This is a bookkeeping failure rather than a
scientific one, but it is unrecoverable without a re-run.
One more, smaller: the seven CNN spectrogram figures further down this page carry a
“CNN prediction (bottom)” legend burned into the image pixels that is false — the
panel does not show what the legend says. This is disclaimed in the prose beside them and the figures have
deliberately not been regenerated, so the erroneous legend remains visible rather than being quietly
repaired.
The 3,156 check
Checked 5 August 2026: an internal audit
flagged 3,156 as a possible copy-paste error, because the same figure appears on this page both as a
recording count and as the bellbird click syllable count. It is a coincidence — both are
correct. Recordings = 3,096 Xeno-Canto (Methods, below) + 60 Koe = 3,156. Clicks = 3,156 of 13,086 bellbird
syllables = 24.1%, consistent with every other row of that table. We record the check here rather than silently
leaving it, so the next reader does not have to repeat it. Note that 3,096 is the raw query result; after
filtering, the clean identified dataset is 2,244 recordings across 175 species.
Rows sum to 13,086. The Click count of
3,156 is identical to the recording count in the page header purely by coincidence — both were
verified independently on 5 August 2026; see the note under the header figures.
29 July 2026
The CNN never categorised syllables
The methods section described the network as segmenting and categorising syllables. It could not categorise: the training script read a frequency field as the class label, giving 829 "classes" for 829 segments. The claim was withdrawn. Segmentation scores were unaffected.
Seven spectrogram figures from that run carry a "CNN prediction" legend although they show human annotations only. They are kept below with the legend uncorrected.
Original correction
Correction (29 July 2026) — this model does not categorise syllables
Until today this section was headed “CNN Segmentation &
Categorisation” and described the network as performing “joint syllable segmentation
(finding boundaries) and categorisation (classifying vocalisation units)”.
No measurement ever supported the categorisation claim, and the model could not have performed the
task. It is withdrawn.
The training script read the Koe annotation field seg[3] as the
syllable class. That field is f_mid — a frequency in Hz, not a label. The result was
829 distinct “classes” over 829 segments: one example per class, the class identities
being floating-point frequencies (690.06, 762.34, 770.07 Hz…). No classifier can be trained that
way, and none was.
The segmentation figures above are unaffected: segmentation scoring uses
only the blank/non-blank distinction, so the spurious classes never enter precision or recall. If anything
they penalise the model, since a segment is terminated whenever the predicted class changes. But every
statement on this page about the network identifying syllable types was false.
Two knock-on errors, corrected today. The dataset table below listed the Koe
corpus as having 3 label types — neither the 829 the model was trained on nor the 74 the corpus
actually contains. And the multi-species section offered bellbird:click as an example of a
species-prefixed label; the real labels in that run are frequencies with a species prefix, e.g.
bellbird:1018.63239577395.
The real taxonomy was never loaded. segment.extraattrvalue.json, sitting
beside the file that was parsed, holds 13 families and 74 labels — Stutter, Alarmy, Pipe,
Flatsqueak, Down, Chortle, Cough. A retrain against it is underway. Until that produces a validated result,
this project has no syllable classifier and no categorisation performance to report.
The model these notes describe (since replaced)
Beyond the rule-based pipeline, we trained a TweetyNet-style convolutional neural network for
syllable segmentation — finding the boundaries of vocal units. It does not categorise
syllables; see the 29 July correction below.
The model processes raw spectrograms and predicts frame-level labels, then post-processing extracts contiguous
segments with confidence thresholds and minimum-duration filtering. This architecture, introduced by
Cohen et al. (2022) for birdsong annotation, learns
spectral-temporal features directly from data rather than relying on hand-crafted rules.
Architecture
Input: Log-scaled spectrogram (500–10kHz, z-score normalised per file)
Output: Frame-level labels (N classes + 1 blank). Only the blank/non-blank distinction is used for segmentation — per the 29 July correction, the class dimension was misconfigured and carries no syllable-type information.
Loss: Weighted Cross-Entropy (blank weight = 0.15–0.25, tuned per species)
Post-processing: Confidence threshold sweep (0.3–0.9), minimum segment duration filtering, IoU > 0.1 matching against ground truth
Multi-Species Training
The CNN trains jointly on annotated datasets from multiple species, with species-prefixed labels to avoid
category collision across corpora. This allows a single model to segment vocalisations across species
with different acoustic structures — bellbird's 55ms discrete syllables vs toutouwai's 971ms sustained
phrases. Correction (29 July 2026): this previously read “segment and categorise” and gave
bellbird:click as an example label. In the run described here the labels are frequencies rather
than call types (e.g. bellbird:1018.63239577395), so no cross-species categorisation was
performed.
Dataset
Species
Recordings
Segments
Label types
Source
Koe
Bellbird (korimako)
60
829
74 †
Fukuzawa et al. (2020)
Donald
Toutouwai (NI robin)
124
10,357
73
Harry Donald, Shaw Lab (VUW)
Campbell
Kākā
—
—
—
Fraser Campbell, Shaw Lab (VUW) — forthcoming
† Corrected 29 July 2026. This
cell previously read “3”. The Koe corpus carries 74 syllable labels across 13 families
(segment.extraattrvalue.json); the CNN described above was mistakenly trained on 829 frequency
values instead. See the 29 July correction.
Data Augmentation
To make the model robust to the heterogeneous recording conditions across datasets — studio (Koe) vs field
(Donald, Campbell) — we apply six augmentation techniques during training, each with 30% probability per sample:
Time stretch (±20%) — handles different phrase/syllable durations across species
Frequency shift (±2 spectrogram bins) — simulates different microphone frequency responses
SpecAugment time masking — forces the model to learn from partial spectrograms (Park et al. 2019)
SpecAugment frequency masking — same, for the frequency axis
Additive Gaussian noise (1–5% of signal std) — simulates varying background noise levels (forest ambient vs studio silence)
Volume jitter (±20%) — handles different microphone distances and recording gains
The figures with the wrong legend
Segmentation Demonstration
The spectrograms below show ground-truth annotations only — the top bands, dotted boundary
lines and category labels are all human annotation. They contain no CNN output. The figure generator
stamped every image with a “CNN prediction (bottom)” legend entry unconditionally, but the run
that produced these images emitted zero predicted segments on all seven examples:
cnn_spectrograms/examples.json records n_pred = 0 for every entry (toutouwai
Felix, for instance, is n_gt = 61, n_pred = 0). The legend printed inside the images is
therefore false — the captions below are the correct description, and the generator has been fixed
so that future figures only claim a prediction band when one exists. CNN overlays will be added when a run
actually produces segments on these files. These examples come from recordings held out of training.
Toutouwai — Felix (Donald dataset)
10s excerpt · 500–10kHz · Ground-truth annotations only · no CNN overlay (this run produced 0 predicted segments)
Toutouwai — Captain (Donald dataset)
10s excerpt · 500–10kHz · Ground-truth annotations only · no CNN overlay (this run produced 0 predicted segments)
Korimako — Koe bellbird (studio recording)
15s excerpt · 500–10kHz · 51 annotated syllables · Ground-truth annotations only · no CNN overlay (this run produced 0 predicted segments)
Ground-truth annotations only, above. Training has
in fact completed — the reason there are no overlays is that the completed run predicted no segments at
all on these seven files, not that it has not been run yet.
27 July 2026
CNN-beats-baseline claims withdrawn
Three claims went. That the CNN's advantage was "more dramatic" on toutouwai: no evaluation existed, and on the one weak test since, the classical baselines win. That the CNN beat the FIR baseline on korimako: the two were scored with different matching rules on different splits. That manual cluster purity was "validated at 91%": the numbers did not reproduce, and the recomputed 99.6% is close to a tautology.
The 0.784 figure itself failed to reproduce. No random seed was set, and a re-run overwrote the original result file.
Original correction: CNN numbers
Correction (27 July 2026) — what the CNN numbers do and do not show
An earlier version of this section claimed the CNN's advantage was
“more dramatic on the Donald toutouwai dataset”, and that the CNN “learns spectral change
patterns that signal phrase boundaries even when the amplitude envelope is flat”.
No measurement supported that claim when it was published — no CNN toutouwai evaluation existed
at the time. The claim is withdrawn. What we can actually say is below.
Toutouwai: the CNN has not yet been validly evaluated, and on the one weak
evaluation that does exist it loses to both classical baselines. The multi-species augmented model
(the architecture described below) scores F1=0.262 (P=0.311, R=0.226) on toutouwai over
13 test files — against FIR F1=0.306 and spectral flux F1=0.329. On the evidence
we have, the classical baselines currently win on toutouwai. That 0.262 is itself a weak
measurement: 13 test files, and the confidence threshold was chosen by taking the argmax over a sweep
run on the very files being scored, so it is not a held-out estimate either. Read it as
“not yet properly measured, and no sign of an advantage” — not as a firm ranking in either
direction. The hypothesis that a CNN should handle toutouwai's sustained tonal phrases (median 971ms)
better than amplitude-envelope methods remains untested.
Bellbird (Koe): F1=0.784 (P=0.753, R=0.818, median boundary error
13.3ms) — from a bellbird-only run, 100 epochs
(cnn_segmentation_results_v3.json). This is not a held-out estimate. That file
contains a configuration, a six-point confidence-threshold sweep, and the argmax over that sweep. There
is no validation split, so the threshold was selected on the same data the score is reported on. 0.784
is an optimistic upper bound on that configuration, and for the same reason it is not directly
comparable to the FIR amplitude-envelope baseline (F1=0.731, 31.5ms boundary error), which had no
equivalent tuning freedom.
The head-to-head against the FIR baseline is withdrawn: the two were not
scored the same way, and on the fairest comparison available the classical method is not behind.
The CNN counts a detection as correct at IoU > 0.1
(tweetynet_v3.py:188); the FIR baseline was held to
IoU ≥ 0.3 or 50% overlap (validate_fir_segmentation.py:201, recorded in its
own output as matching_criteria). The quoted 0.731 is also FIR's test-split row
(376 ground-truth segments), while the CNN's 0.784 is over a different split (499 segments). Scored
across the full 829-segment dataset at its stricter threshold, FIR reaches F1=0.786
(P=0.857, R=0.725) — level with the CNN's 0.784 while being judged more harshly. Until both are
re-scored on one split under one matching criterion, treat the CNN as not demonstrated to beat the
classical baseline on bellbird.
Reproducibility: the artifact behind 0.784 no longer exists, and the number does
not reproduce. None of the training scripts set a torch seed — only the file-level split is
seeded — so weight initialisation and batch shuffling differ on every run. On 27 July 2026 the
same script was re-run on the same data and wrote to the same filename, replacing the artifact this
figure was read from; the re-run scored F1=0.767 (P=0.726, R=0.814) at the same selected
threshold of 0.3. The originally published values survive only in a snapshot taken minutes beforehand.
We report this rather than quietly restating the new number, because the honest content of the finding
is that this measurement has a run-to-run spread we never characterised, and that results were
being overwritten in place instead of written to run-stamped paths.
Our two bellbird runs disagree and we cannot yet reconcile them.
A separate 50-epoch bellbird run over 15 test files (cnn_bellbird_large.json) gives
F1=0.361 (P=0.638, R=0.251, median boundary error 49.7ms) on the same dataset. The two runs differ
in epoch count, spectrogram settings and minimum-segment duration, and share no defined test split, so
neither supersedes the other. Until a run with a proper held-out split settles it, treat bellbird
segmentation performance as unresolved between 0.361 and 0.784, and treat 0.784 as the most
favourable configuration we have run rather than as the headline result.
The multi-species architecture below is a different, worse model — do not
attach 0.784 to it. The joint multi-species training and augmentation described in the rest of this
section correspond to cnn_multispecies_augmented.json, whose combined score is
F1=0.259 (P=0.311, R=0.222): bellbird F1=0.308 on 2 test files, toutouwai F1=0.262 on 13.
The 0.784 figure came from the bellbird-only model and says nothing about this configuration.
Original correction: cluster purity
Correction (27 July 2026). This panel previously read
“manual cluster purity validated at 91% overall (Chortle 100%, Down 98%, Stutter 97%)”.
None of those three per-category numbers reproduce, and neither does the 91%. Recomputed
directly from the deployed bellbird_pca_data.json over its 241 manually clustered points,
purity against the Koe/Webb family labels is 99.6% (240/241): Chortle 100% (24/24),
Down 100% (36/36), Stutter 100% (79/79), Flatsqueak 100% (25/25), Peaksqueak 100% (19/19),
Cough 100% (12/12), Cough + Click 100% (12/12), Alarmy 100% (9/9), Stepup 100% (7/7),
and Pipe 94.4% (17/18) — one Pipe point carries the family label Alarmy, and it is the only
disagreement. We are also downgrading the word “validated”: the manual clusters were drawn
with the family labels visible, so near-perfect purity is close to a tautology and carries almost no
information about whether the categories are real.
The figure that does carry information — seed-label agreement.
For the 575 clips the DTW template matcher labelled on its own, agreement between its assignment
and the clip's original Koe/Webb family label is 35.8% (206/575). Broken out by the category the
matcher assigned:
Assigned category
Agreement
n assigned
Stepup
7%
114
Pipe
29%
133
Flatsqueak
29%
99
Stutter
45%
67
Chortle
53%
17
Peaksqueak
58%
33
Alarmy
58%
53
Cough + Click
63%
30
Down
77%
26
Cough
100%
3
In the pipeline's own words this is a “sanity, not accuracy”
check, and that hedge is correct: the template categories and the Koe/Webb families are different
schemes, so disagreement is not automatically error. But Stepup agreeing on 7% of the 114 clips it
was assigned is the single most useful number on this page, and it was being computed on every run
and never shown. It says the Stepup template is very likely matching something other than Stepup, and
that those 114 labels should not be relied on. Treat every category above as provisional in proportion
to its agreement.
Method note: agreement counts
Flatspeak → Flatsqueak as a match (they are the same call type — see the
spelling correction) and Cough + Click → Cough (Cough + Click
is a Cough sub-type). Compared as raw strings without those two equivalences the overall figure is
27.5% (158/575), which is what dtw_classify.py prints today.
July 2026
Tūī classifier reordered; samples doubled
The first tūī classifier put 55% of syllables in "low-frequency" because it checked frequency before tonal quality. Checking tonal quality first brought that to 0.6%, in line with Hill. The samples were later doubled (tūī to 232 recordings, korimako to 94, kākā to 47). The notes below give the earlier korimako sample as both 46 and 40: the analysis used 46 recordings (data_v2.json), while the sample-size curve was computed on 40. Tūī proportions held; korimako stutter fell from 62.8% to 56.1% and click rose from 19.4% to 24.1%.
Original notes
v2 classifier improvements: The v1 analysis over-assigned "low-frequency" syllables (55%) due to a threshold-ordering
artefact — syllables with low f₀ but strong upper harmonics were caught by the frequency check before reaching the harmonicity check.
The restructured classifier checks tonal quality first, then frequency, reducing low-frequency to 0.6% of tūī syllables (unchanged from the first v2 pass, now confirmed on a doubled sample) —
consistent with Hill's finding that these are relatively rare.
v2 Improvement
The v1 classifier over-assigned "low-frequency" (55%) due to checking f₀ before harmonicity —
syllables with low fundamental but strong upper harmonics were misclassified. The v2 classifier
checks tonal quality first, then frequency, bringing low-frequency down to 0.6% — consistent with
Hill's finding that these are relatively rare. RMNR (64.7%) is now the dominant category, followed by
trill (17.5%) and harmonic (13.8%). These proportions are stable from the first v2 pass (116 recordings)
to the doubled sample (232 recordings). No harsh syllables were detected — these are quiet, close-range
vocalisations that field recorders may not capture.
All three species reach stable entropy by ~15–20 recordings. Tūī (now 232 recordings, was 116) and korimako (now 94, was 40) are well past the plateau.
Kākā (now 47, was 25) has also cleared it comfortably — no longer sitting right at the threshold. Sample sizes across all three species doubled this session;
this confirms that our sample sizes are adequate for characterising the proportional distribution of vocalisation types —
though not necessarily for capturing rare types (e.g., the absent shraak calls). Note: the rarefaction curve chart below still reflects the pre-expansion
sample sizes (116/40/25) — a rebuild with the doubled corpus is queued as follow-up work; the qualitative conclusion (all species plateau well before their full N) is expected to hold and, if anything, strengthen.
✓ Full tūī analysis: All 232 A-quality song recordings analysed — 36,268 syllables across 5 types (doubled from 116/17,716 this session; distribution essentially unchanged, confirming the smaller sample wasn't distorting the tūī findings).
✓ Korimako comparison: 94 A-quality recordings (doubled from 46), 13,086 syllables. Stutter still dominates but dropped from 62.8%→56.1% as click grew 19.4%→24.1% — a real shift with the larger sample, not noise.
✓ Kākā comparison: 47 A-quality recordings (doubled from 25), 1,790 calls. Simpler call-dominated repertoire vs honeyeater song; rule-classifier call counts were withdrawn on 2026-09-03 after the categories failed validation.
✓ Geographic variation: Now 13 regions for tūī with the doubled sample (was 10). Prose below reflects the original 116-recording pass — regional breakdowns are queued for a refresh with the new 232-recording data (see Methodology note).
✓ Unsupervised clustering: HDBSCAN on 32-dim MFCC+spectral features. Resolved the low-frequency
discrepancy: 93.9% of "low-frequency" syllables have centroids above 2kHz — it's a threshold-ordering
artefact in our rule-based classifier, not a biological disagreement with Hill.
✓ Data-driven korimako categories: On the Koe dataset, 818 syllables were PCA-embedded (spike-sorting
style), manually clustered into 10 categories, then DTW-barycenter templates classified the rest — feeding
the song-structure analysis (transitions, motifs, sex & site differences). Explore it via the
PCA clustering tool and annotation tool.
✓ Korimako sex & song: Site-honest sex classifier (leave-one-island-out) shows the male↔female
song difference generalises across dialects — 80.5% on never-seen islands vs 59.5% chance — so it isn't a
site artefact. A bird's position on that axis is a stable individual trait (repeatability ICC = 0.67);
feature attribution + a length ablation show intermediacy is genuine multi-feature sex-atypicality, not song
length. Flags a small non-binary group and a rarer sex-atypical ("trans") group as leads for audio audit.
See the Sex & Song section under Vocalisation → Korimako.
Future work — temporal analysis: How has the XC archive's tūī song changed over decades? Do more recent recordings capture different repertoires? Seasonal and temporal patterns will be explored in a future species-specific analysis.
Next — tūī template matching: Apply the same PCA → manual-cluster → DTW-template pipeline used for
korimako to tūī, and extend to additional species (tīeke, kōkako) and datasets (AviaNZ kiwi).
Every earlier version of this page is in the
git history.